AI and Software
Links
Abstract
Software is at the frontier of change for AI.
Drawing on The Atomic Human, this keynote starts by giving a clear model of what machine intelligence is and is not, then applies that model to the software industry: how generative systems alter information flows inside the firm, why superficial automation can hollow out expertise, and how intellectual and agentic debt accumulate when organisations ship faster than they can explain. The talk introduces the judgment layer — the organisational interface where human authority still owns consequence — and how we retain it in an age of AI-generated code. It closes with Trent, where we are putting that idea into practice for complex software systems.
Opening: Software Advantage When Code Gets Cheap
Welcome. Thirty minutes on how AI is reshaping software businesses — and where advantage will sit as the cost of producing software falls. I will keep this practical for founders, CEOs, and investors: what to automate, what not to, and what debt you accumulate if you get the balance wrong. The through-line is the judgment layer: the part of the organisation that still owns consequence when machines act. I will end with how we are building for that at Trent. Happy to go deeper in the Q&A that follows.
Three beats. First, a model of machine versus human intelligence — without it, SaaS strategy drifts into hype. Second, what that means for software businesses today: product, delivery, and organisational design. Third, how the industry evolves when agents act: the judgment layer must become explicit, or agentic debt accumulates. I close with Trent — where we put that architecture into practice.
Part 1: What AI Is (and Isn’t) for Software Businesses
Henry Ford’s Faster Horse
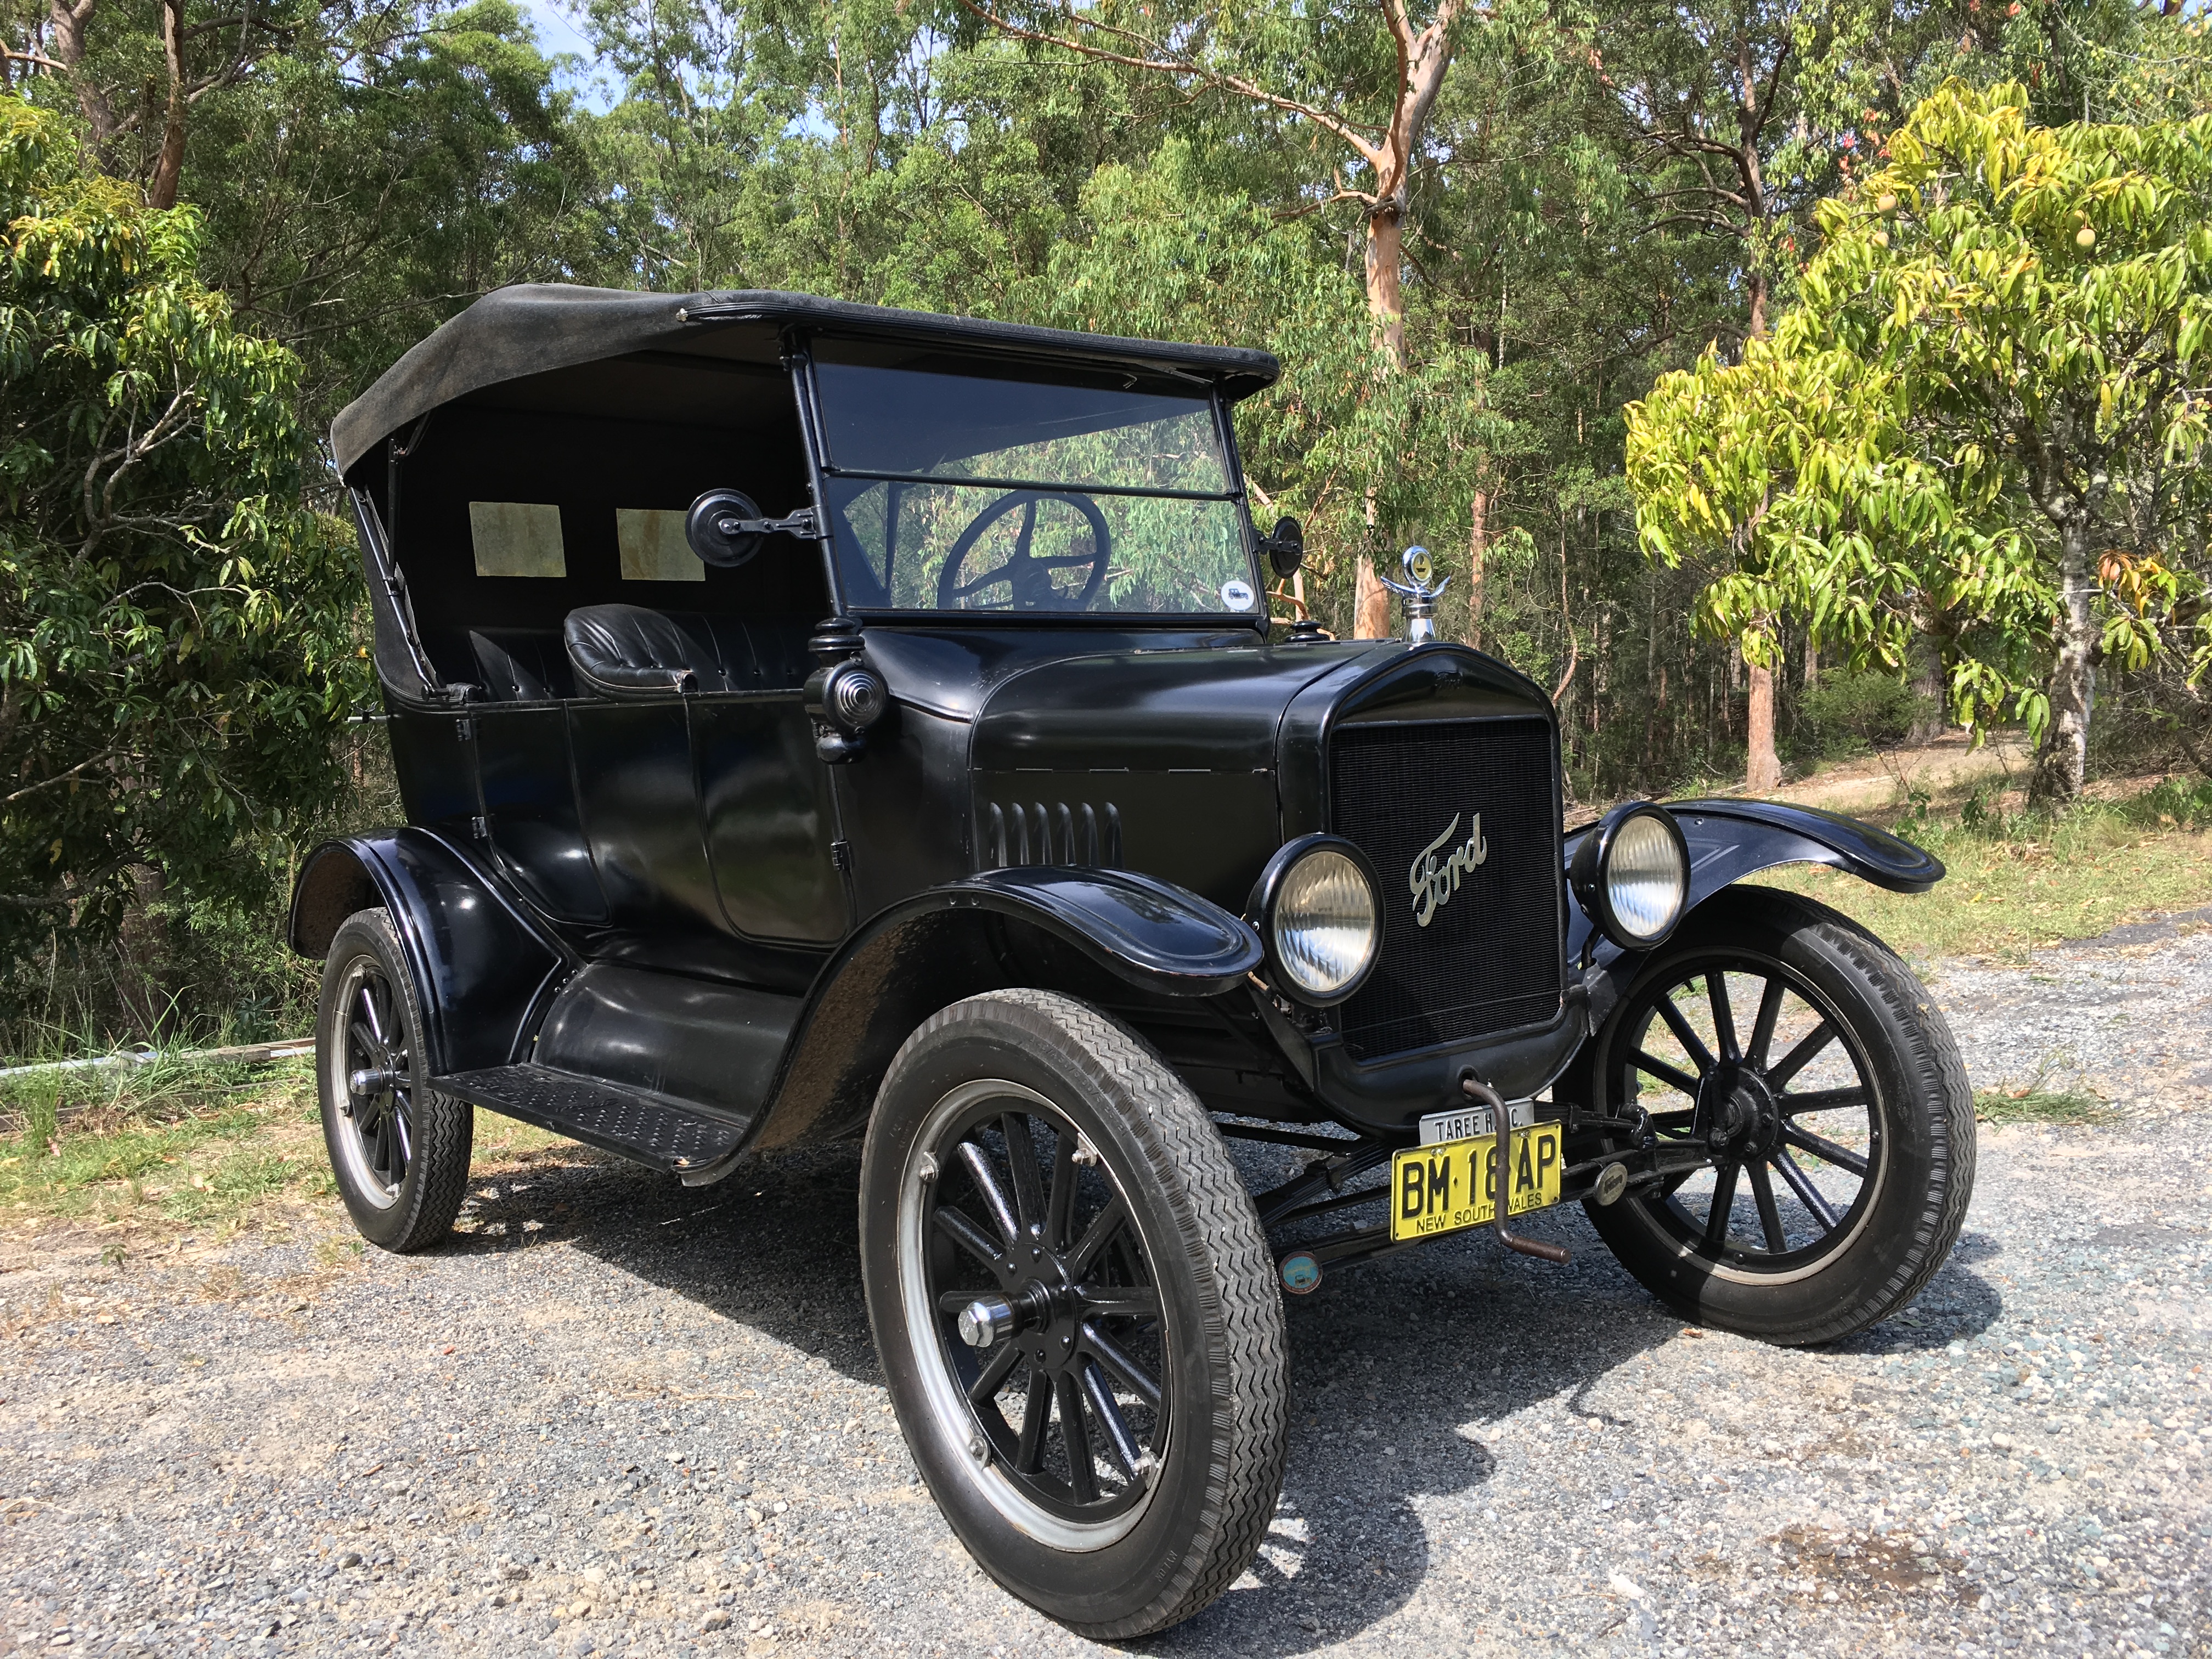
Figure: A 1925 Ford Model T built at Henry Ford’s Highland Park Plant in Dearborn, Michigan. This example now resides in Australia, owned by the founder of FordModelT.net. From https://commons.wikimedia.org/wiki/File:1925_Ford_Model_T_touring.jpg

It’s said that Henry Ford’s customers wanted a “a faster horse.” If Henry Ford was selling us artificial intelligence today, what would the customer call for, “a smarter human?” That’s certainly the picture of machine intelligence we find in science fiction narratives, but the reality of what we’ve developed is much more mundane.
Car engines produce prodigious power from petrol. Machine intelligences deliver decisions derived from data. In both cases the scale of consumption enables a speed of operation that is far beyond the capabilities of their natural counterparts. Unfettered energy consumption has consequences in the form of climate change. Does unbridled data consumption also have consequences for us?
If we devolve decision making to machines, we depend on those machines to accommodate our needs. If we don’t understand how those machines operate, we lose control over our destiny. Our mistake has been to see machine intelligence as a reflection of our intelligence. We cannot understand the smarter human without understanding the human. To understand the machine, we need to better understand ourselves.
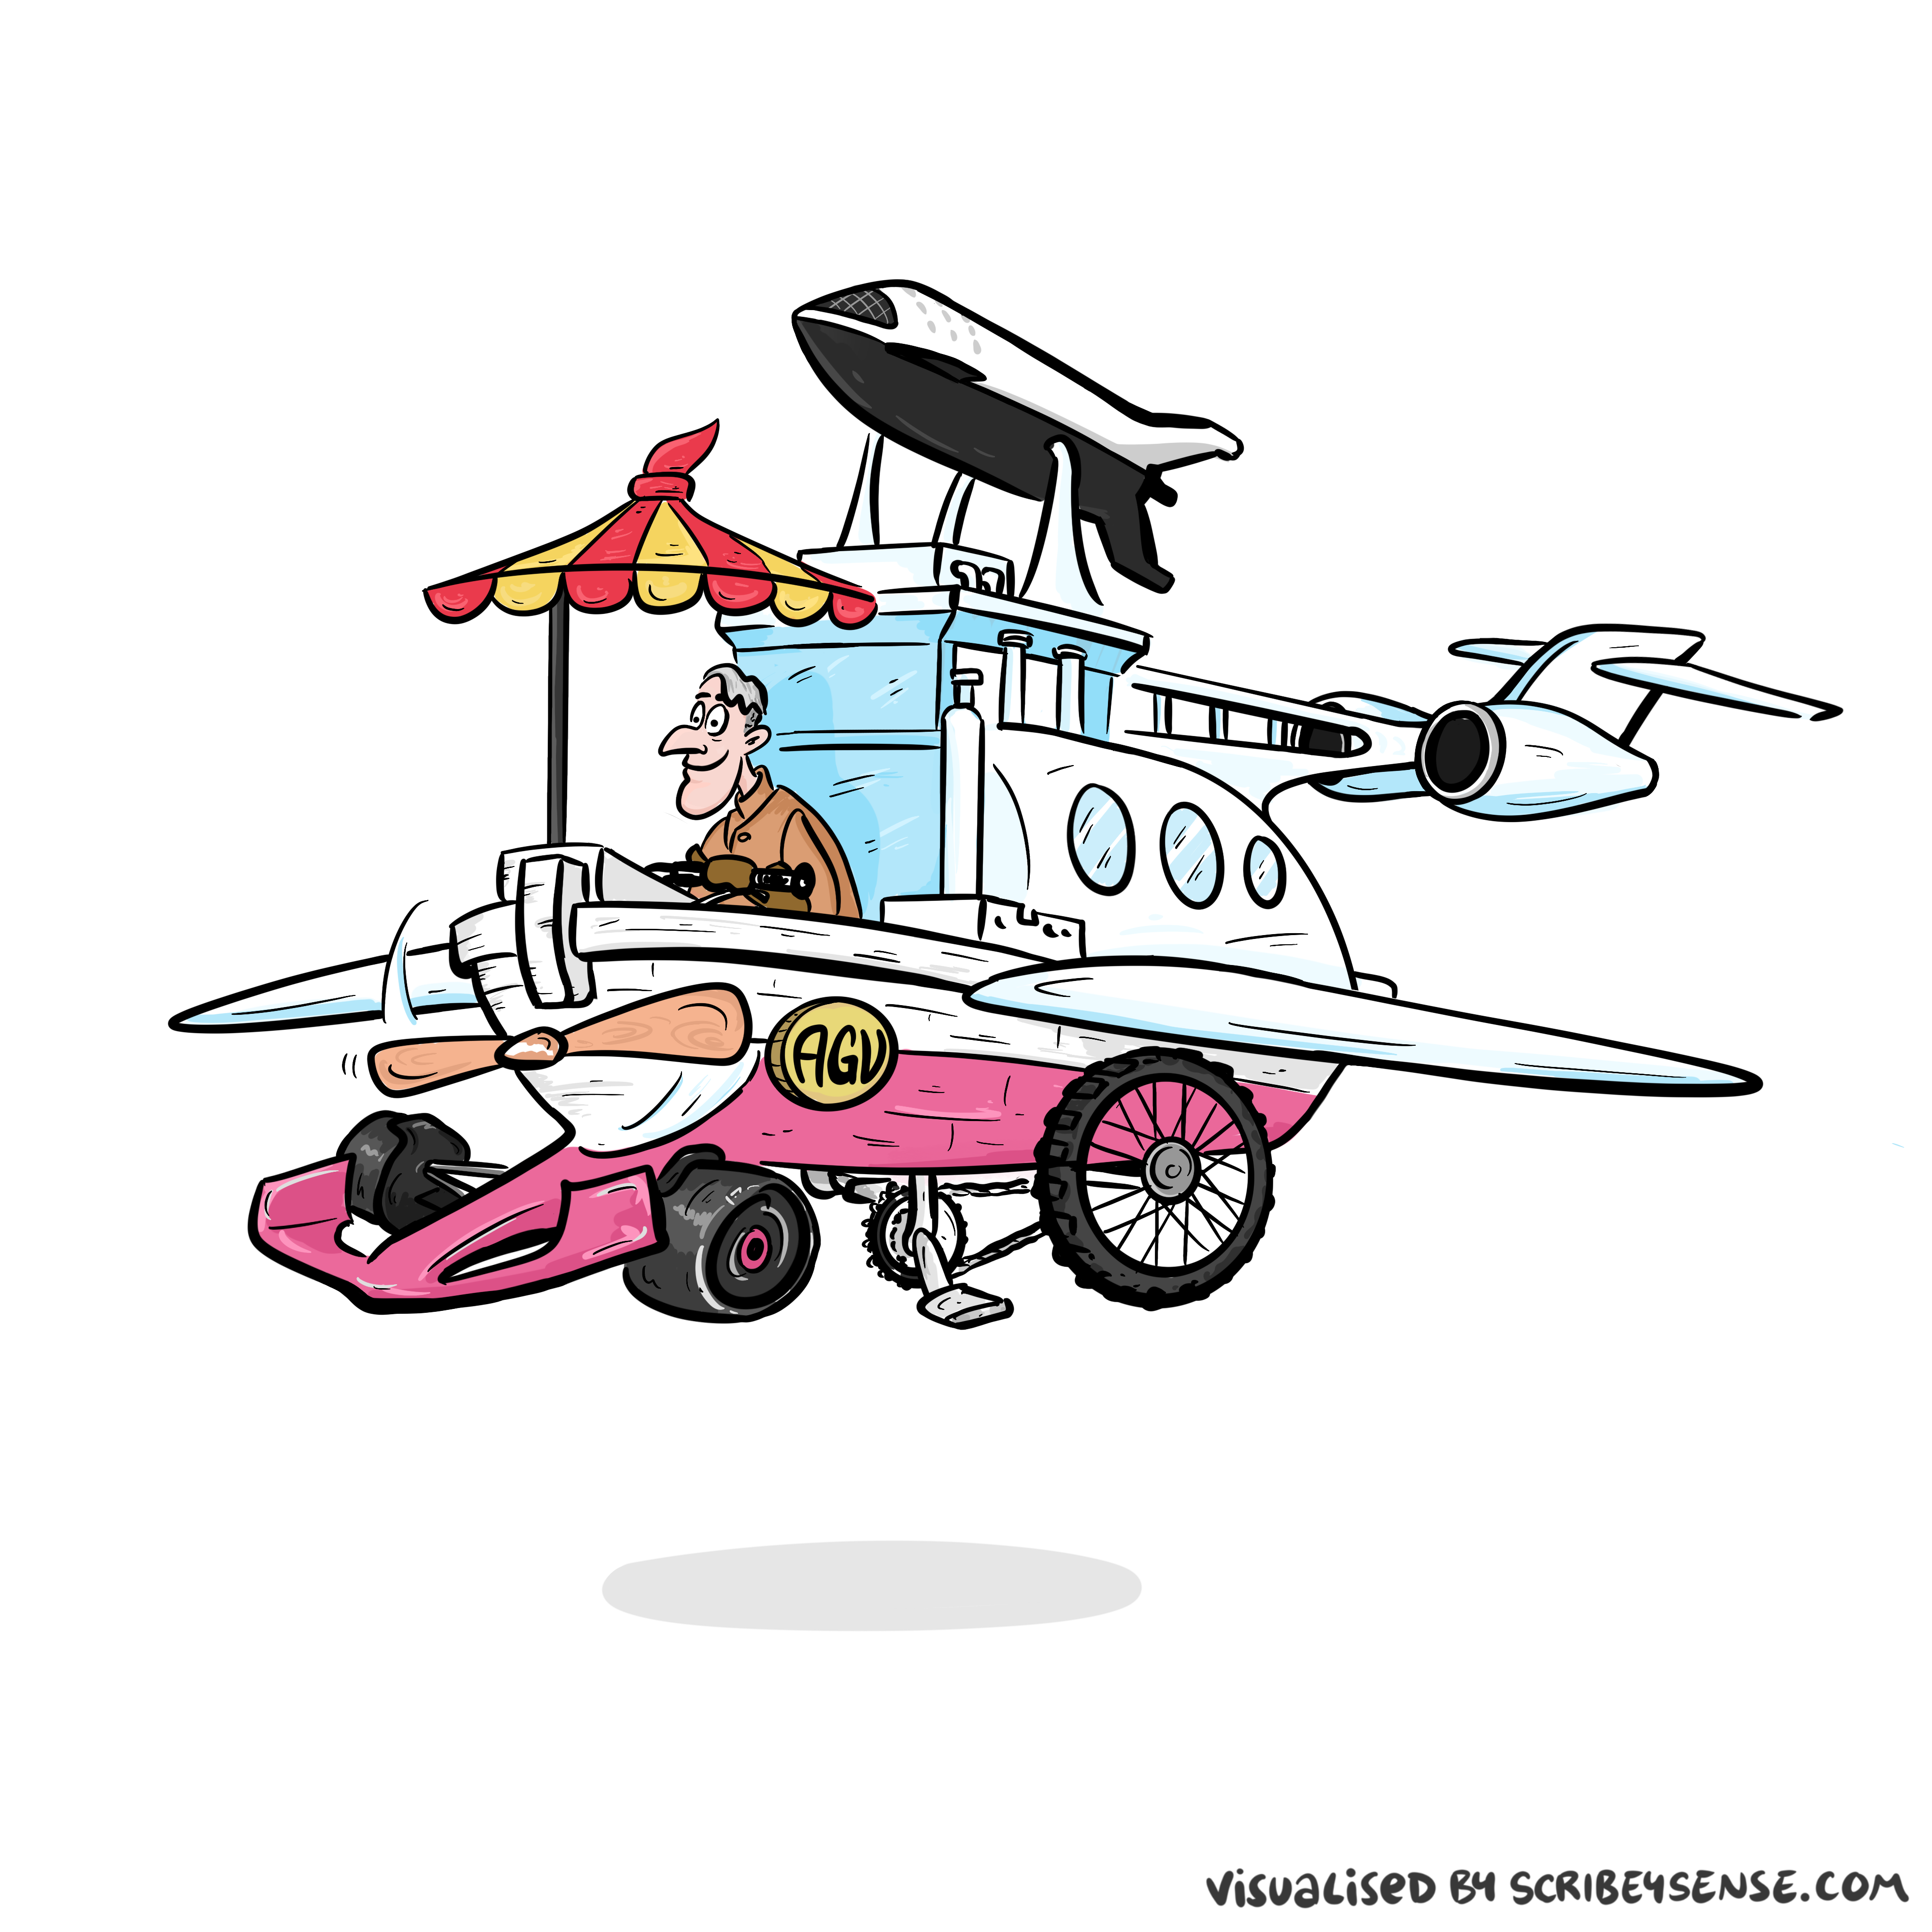
Figure: The notion of artificial general intelligence is as absurd as the notion of an artificial general vehicle - no single vehicle is optimal for every journey. (Illustration by Dan Andrews inspired by a conversation about “The Atomic Human” Lawrence (2024))
This illustration was created by Dan Andrews inspired by a conversation about “The Atomic Human” book. The drawing emerged from discussions with Dan about the flawed concept of artificial general intelligence and how it parallels the absurd idea of a single vehicle optimal for all journeys. The vehicle itself is inspired by shared memories of Professor Pat Pending in Hanna Barbera’s Wacky Races.
The Atomic Human
Figure: The Atomic Eye, by slicing away aspects of the human that we used to believe to be unique to us, but are now the preserve of the machine, we learn something about what it means to be human.
The development of what some are calling intelligence in machines, raises questions around what machine intelligence means for our intelligence. The idea of the atomic human is derived from Democritus’s atomism.
In the fifth century bce the Greek philosopher Democritus posed a question about our physical universe. He imagined cutting physical matter into pieces in a repeated process: cutting a piece, then taking one of the cut pieces and cutting it again so that each time it becomes smaller and smaller. Democritus believed this process had to stop somewhere, that we would be left with an indivisible piece. The Greek word for indivisible is atom, and so this theory was called atomism.
The Atomic Human considers the same question, but in a different domain, asking: As the machine slices away portions of human capabilities, are we left with a kernel of humanity, an indivisible piece that can no longer be divided into parts? Or does the human disappear altogether? If we are left with something, then that uncuttable piece, a form of atomic human, would tell us something about our human spirit.
See Lawrence (2024) atomic human, the p. 13.
Information and Embodiment
Figure: Claude Shannon (1916-2001)
| bits/min | billions | 2,000 |
| billion calculations/s | ~100 | a billion |
| embodiment | 20 minutes | 5 billion years |
Figure: Embodiment factors are the ratio between our ability to compute and our ability to communicate. Relative to the machine we are also locked in. In the table we represent embodiment as the length of time it would take to communicate one second’s worth of computation. For computers it is a matter of minutes, but for a human, it is a matter of thousands of millions of years.
Embodiment Factors: Walking vs Light Speed
Imagine human communication as moving at walking pace. The average person speaks about 160 words per minute, which is roughly 2000 bits per minute. If we compare this to walking speed, roughly 1 m/s we can think of this as the speed at which our thoughts can be shared with others.
Compare this to machines. When computers communicate, their bandwidth is 600 billion bits per minute. Three hundred million times faster than humans or the equiavalent of \(3 \times 10 ^{8}\). In twenty minutes we could be a kilometer down the road, where as the computer can go to the Sun and back again..
This difference is not just only about speed of communication, but about embodiment. Our intelligence is locked in by our biology: our brains may process information rapidly, but our ability to share those thoughts is limited to the slow pace of speech or writing. Machines, in comparison, seem able to communicate their computations almost instantaneously, anywhere.
So, the embodiment factor is the ratio between the time it takes to think a thought and the time it takes to communicate it. For us, it’s like walking; for machines, it’s like moving at light speed. This difference means that most direct comparisons between human and machine need to be carefully made. Because for humans not the size of our communication bandwidth that counts, but it’s how we overcome that limitation..
Figure: Conversation relies on internal models of other individuals.
Figure: Misunderstanding of context and who we are talking to leads to arguments.
Embodiment factors imply that, in our communication between humans, what is not said is, perhaps, more important than what is said. To communicate with each other we need to have a model of who each of us are.
To aid this, in society, we are required to perform roles. Whether as a parent, a teacher, an employee or a boss. Each of these roles requires that we conform to certain standards of behaviour to facilitate communication between ourselves.
Control of self is vitally important to these communications.
The consequences between this mismatch of power and delivery are to be seen all around us. Because, just as driving an F1 car with bicycle wheels would be a fine art, so is the process of communication between humans.
If I have a thought and I wish to communicate it, I first need to have a model of what you think. I should think before I speak. When I speak, you may react. You have a model of who I am and what I was trying to say, and why I chose to say what I said. Now we begin this dance, where we are each trying to better understand each other and what we are saying. When it works, it is beautiful, but when mis-deployed, just like a badly driven F1 car, there is a horrible crash, an argument.
A Six Word Novel
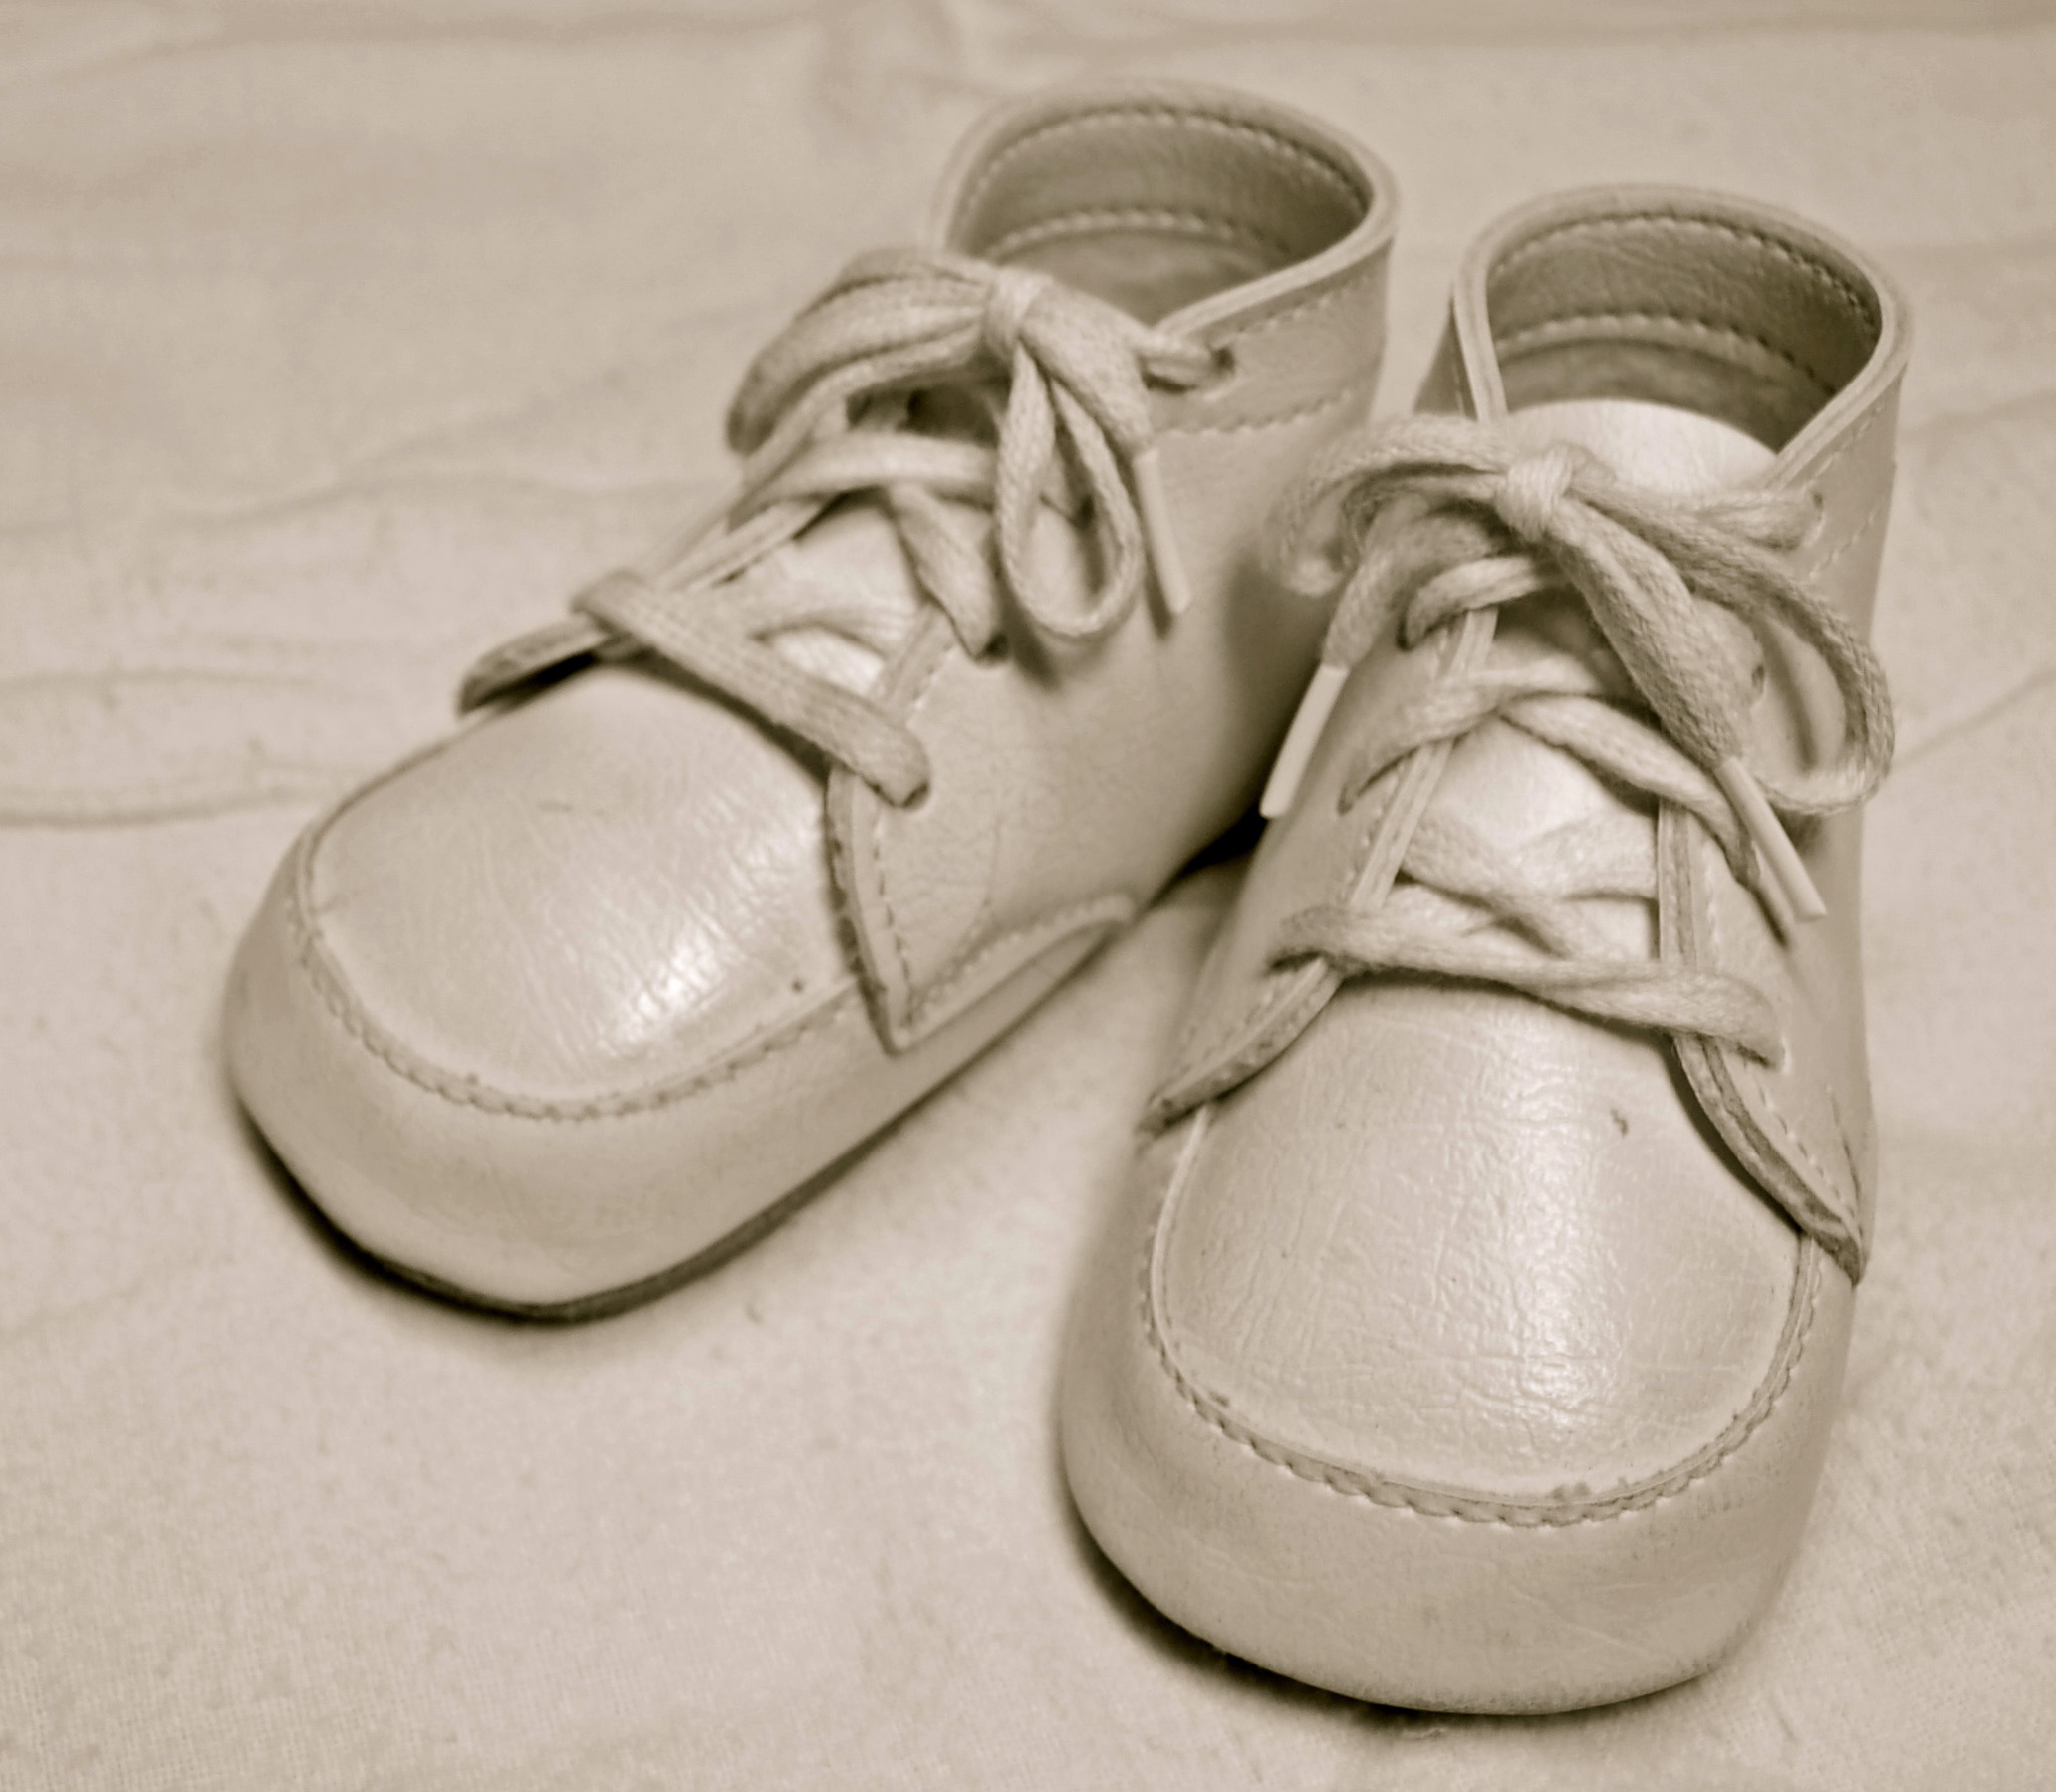
Figure: Consider the six-word novel, apocryphally credited to Ernest Hemingway, “For sale: baby shoes, never worn.” To understand what that means to a human, you need a great deal of additional context. Context that is not directly accessible to a machine that has not got both the evolved and contextual understanding of our own condition to realize both the implication of the advert and what that implication means emotionally to the previous owner.
See Lawrence (2024) baby shoes p. 368.
But this is a very different kind of intelligence than ours. A computer cannot understand the depth of the Ernest Hemingway’s apocryphal six-word novel: “For Sale, Baby Shoes, Never worn,” because it isn’t equipped with that ability to model the complexity of humanity that underlies that statement.
Homo Atomicus
We won’t find the atomic human in the percentage of A grades that our children are achieving at schools or the length of waiting lists we have in our hospitals. It sits behind all this. We see the atomic human in the way a nurse spends an extra few minutes ensuring a patient is comfortable or a bus driver pauses to allow a pensioner to cross the road or a teacher praises a struggling student to build their confidence.
We need to move away from homo economicus towards homo atomicus.
For software businesses, the Atomic Human is a strategy filter. If a capability is easily automated — code generation, boilerplate support, routine analytics — it will not remain a durable differentiator. Advantage concentrates in what remains irreducibly human: product judgment under uncertainty, customer trust, category creation, and the organisational culture that turns software into a business.
The industry is discovering that generating software is becoming cheaper and faster. That is not the same as knowing which software to build, for whom, and with what accountability when it fails. The judgment layer is that accountability: the organisational interface where human authority still decides. Investors should separate companies that use AI to ship more of the same from those that redesign the business around a legible judgment layer.
Part 2: How AI Is Reshaping SaaS
The SaaS model was built on recurring revenue for software that was expensive to write, hard to copy, and delivered through a subscription relationship. Generative AI attacks the first two assumptions and stresses the third.
Philosopher’s Stone
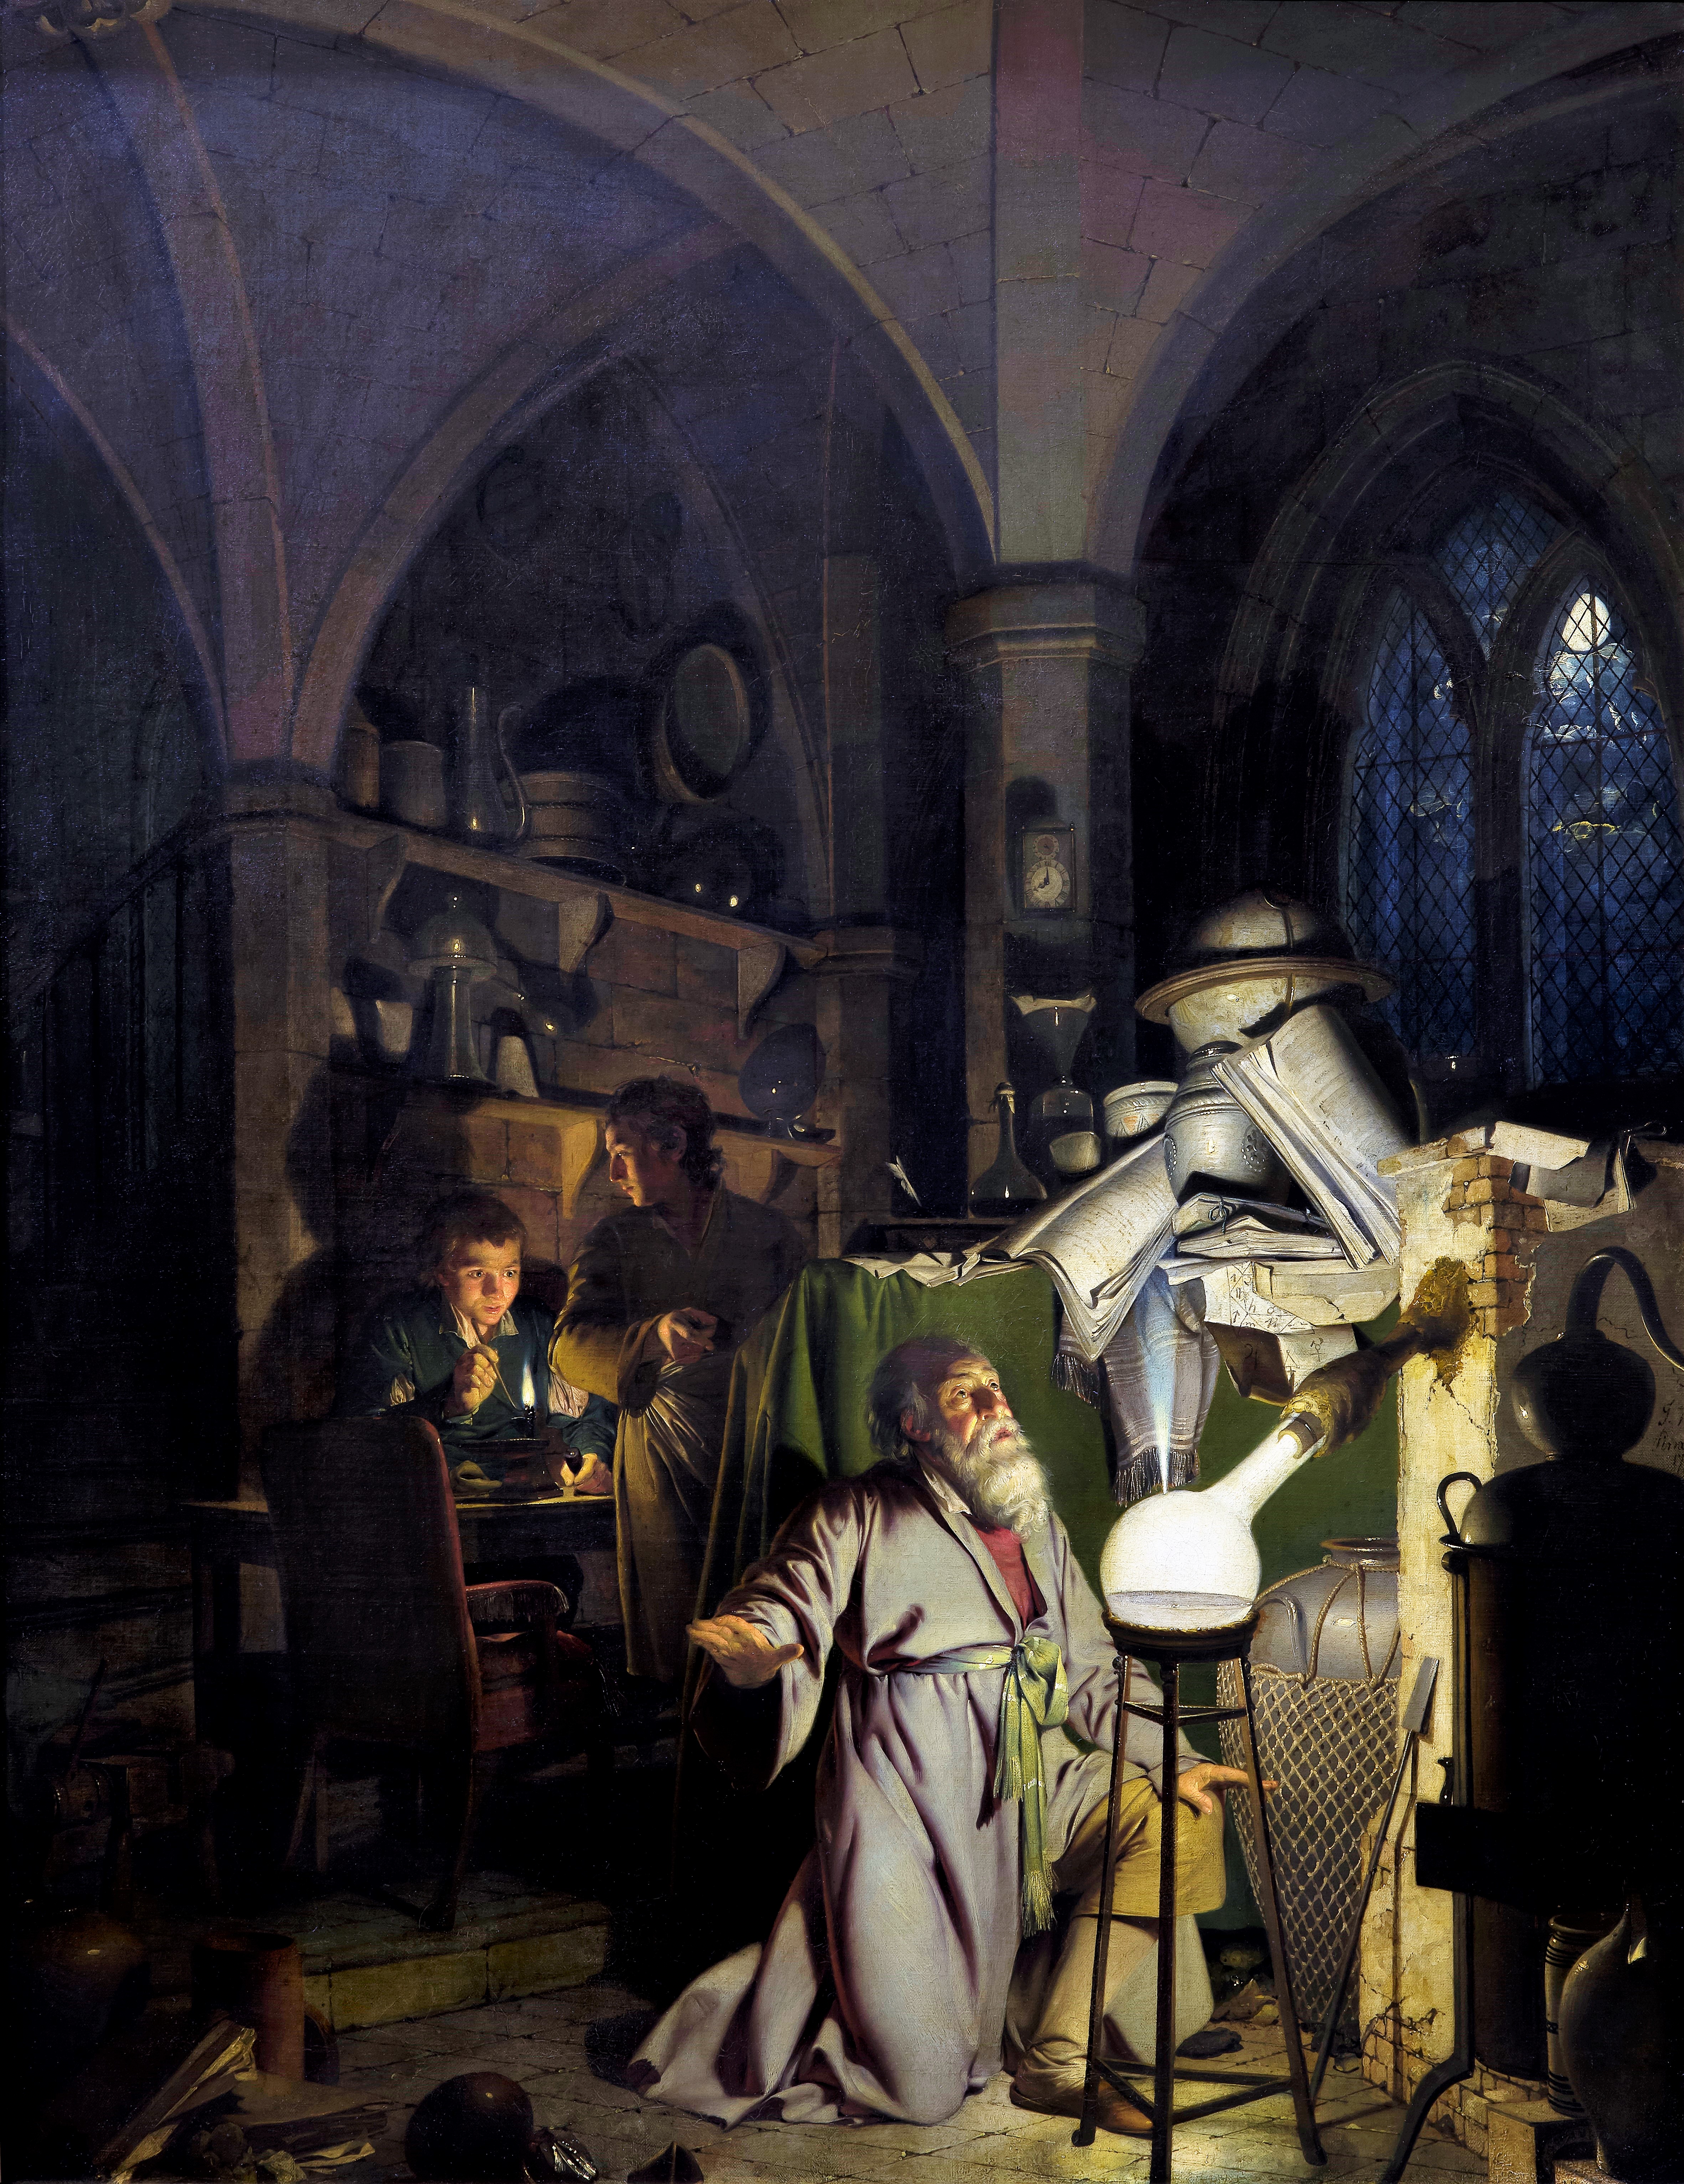
Figure: The Alchemist by Joseph Wright of Derby (1771). The picture depicts Hennig Brand discovering the element phosphorus when searching for the Philosopher’s Stone.
The philosopher’s stone is a mythical substance that can convert base metals to gold.
The Great AI Fallacy
There is a lot of variation in the use of the term artificial intelligence. I’m sometimes asked to define it, but depending on whether you’re speaking to a member of the public, a fellow machine learning researcher, or someone from the business community, the sense of the term differs.
However, underlying its use I’ve detected one disturbing trend. A trend I’m beginining to think of as “The Great AI Fallacy.”
The fallacy is associated with an implicit promise that is embedded in many statements about Artificial Intelligence. Artificial Intelligence, as it currently exists, is merely a form of automated decision making. The implicit promise of Artificial Intelligence is that it will be the first wave of automation where the machine adapts to the human, rather than the human adapting to the machine.
How else can we explain the suspension of sensible business judgment that is accompanying the hype surrounding AI?
This fallacy is particularly pernicious because there are serious benefits to society in deploying this new wave of data-driven automated decision making. But the AI Fallacy is causing us to suspend our calibrated skepticism that is needed to deploy these systems safely and efficiently.
The problem is compounded because many of the techniques that we’re speaking of were originally developed in academic laboratories in isolation from real-world deployment.
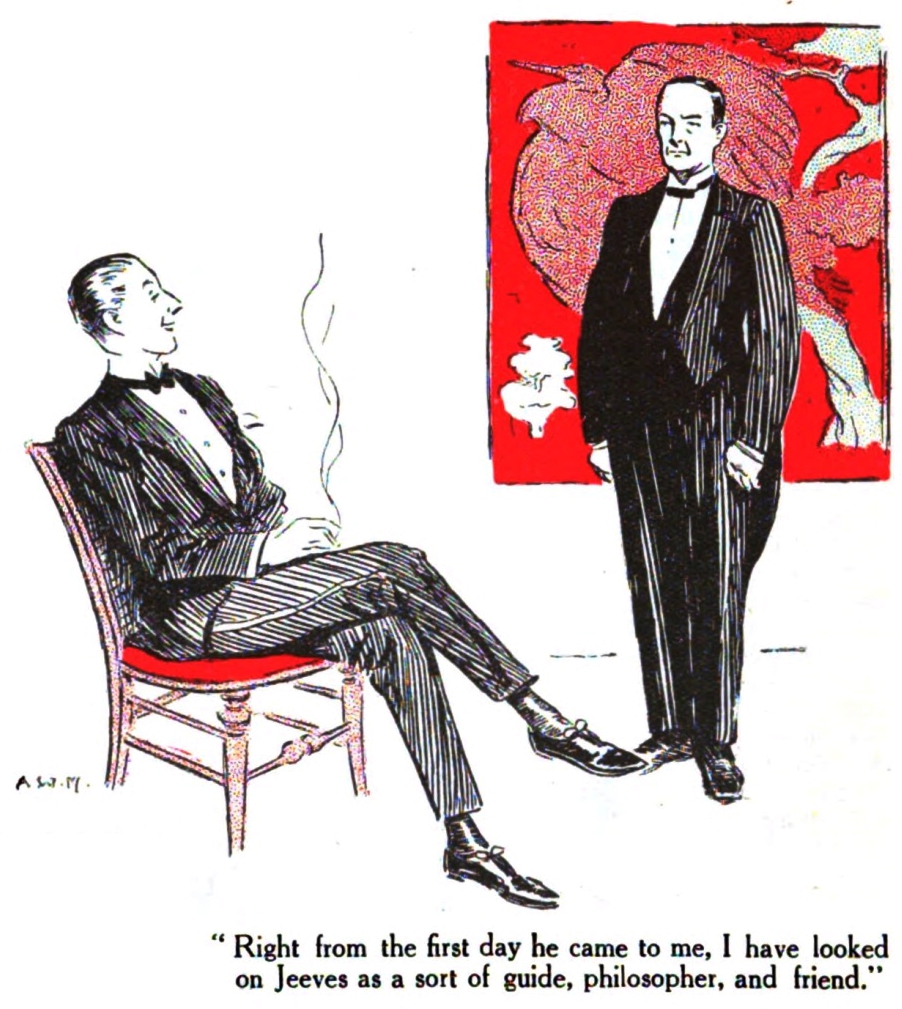
Figure: We seem to have fallen for a perspective on AI that suggests it will adapt to our schedule, rather in the manner of a 1930s manservant.
The Attention Economy
Human intelligence is locked-in. It’s bandwidth restricted. This makes it a bottleneck in the attention economy.
Herbert Simon on Information
What information consumes is rather obvious: it consumes the attention of its recipients. Hence a wealth of information creates a poverty of attention …
Simon (1971)
The attention economy was a phenomenon described in 1971 by the American computer scientist Herbert Simon. He saw the coming information revolution and wrote that a wealth of information would create a poverty of attention. Too much information means that human attention becomes the scarce resource, the bottleneck. It becomes the gold in the attention economy.
The power associated with control of information dates back to the invention of writing. By pressing reeds into clay tablets Sumerian scribes stored information and controlled the flow of information.
New Flow of Information
Classically the field of statistics focused on mediating the relationship between the machine and the human. Our limited bandwidth of communication means we tend to over-interpret the limited information that we are given, in the extreme we assign motives and desires to inanimate objects (a process known as anthropomorphizing). Much of mathematical statistics was developed to help temper this tendency and understand when we are valid in drawing conclusions from data.
Figure: The trinity of human, data, and computer, and highlights the modern phenomenon. The communication channel between computer and data now has an extremely high bandwidth. The channel between human and computer and the channel between data and human is narrow. New direction of information flow, information is reaching us mediated by the computer. The focus on classical statistics reflected the importance of the direct communication between human and data. The modern challenges of data science emerge when that relationship is being mediated by the machine.
Data science brings new challenges. In particular, there is a very large bandwidth connection between the machine and data. This means that our relationship with data is now commonly being mediated by the machine. Whether this is in the acquisition of new data, which now happens by happenstance rather than with purpose, or the interpretation of that data where we are increasingly relying on machines to summarize what the data contains. This is leading to the emerging field of data science, which must not only deal with the same challenges that mathematical statistics faced in tempering our tendency to over interpret data but must also deal with the possibility that the machine has either inadvertently or maliciously misrepresented the underlying data.
See Lawrence (2024) topography, information p. 34-9, 43-8, 57, 62, 104, 115-16, 127, 140, 192, 196, 199, 291, 334, 354-5. See Lawrence (2024) anthropomorphization (‘anthrox’) p. 30-31, 90-91, 93-4, 100, 132, 148, 153, 163, 216-17, 239, 276, 326, 342.
How Information Flows in Organisations
The information topography of an organisation is how information flows through the organisaiton. At one level this will involve a hierarchy of information propagation: the chart of reporting lines. But alongside this there are other mechanisms to share information.
This dictates the organisations "absorbtive capacity which in turn dictates how it will make decisions. The nature of decisio of decisions depend on how well the information that feeds them can travel.
The three components of the information topography: storage, channel and coupling come together to form the information topography.
Classically information propagates through two principle patterns. Hub-and-spoke networks, and peer-to-peer meshes. The hub-and-spoke becomes a hierarchy as it scales. The different mechanisms have different implications for bandwidth, latency, and resilience.
Figure: In a classical corporate hierarchy, information travels vertically. Strategic decisions flow downward from the CEO through the C-suite (CFO, CIO, COO) to functional departments. Data and reports flow upward. External signals from customers and markets enter at the top. Each layer introduces delay and compression.
The hub-and-spoke model centralises information processing. All communication between departments routes through a central function. This works well for “command and control” but the central node tends to become overloaded. In practive that’s why we obtain a hierarchy so each spoke is itself a hub for the next level.
Figure: In a hub-and-spoke model, all information routes through a central node. This can result in low latency (good command and control) but the central hub can become overloaded.
Peer-to-peer structures allow direct communication between teams without a central intermediary. This maximises bandwidth and reduces latency, but requires more communication interfaces than are managed with hub-and-spoke. Amazon’s API mandate — requiring all teams to expose their capabilities through programmatic interfaces — is an example of deliberately engineering a peer-to-peer information structure within a large organisation. The challenge is coordination: without a hub, norms and protocols must emerge from the network itself. This is where culture becomes important
Figure: In a peer-to-peer network, teams communicate directly with each other through adjacent and cross-cutting channels, without routing through a central authority. This structure is resilient and high-bandwidth, but requires shared protocols and trust. It mirrors how open-source software communities and federated data ecosystems operate.
The API Mandate
The API Mandate was a memo issued by Jeff Bezos in 2002. Internet folklore has the memo making five statements:
- All teams will henceforth expose their data and functionality through service interfaces.
- Teams must communicate with each other through these interfaces.
- There will be no other form of inter-process communication allowed: no direct linking, no direct reads of another team’s data store, no shared-memory model, no back-doors whatsoever. The only communication allowed is via service interface calls over the network.
- It doesn’t matter what technology they use.
- All service interfaces, without exception, must be designed from the ground up to be externalizable. That is to say, the team must plan and design to be able to expose the interface to developers in the outside world. No exceptions.
The mandate marked a shift in the way Amazon viewed software, moving to a model that dominates the way software is built today, so-called “Software-as-a-Service.”
Any organization that designs a system (defined broadly) will produce a design whose structure is a copy of the organization’s communication structure.
Conway (n.d.)
The law is cited in the classic software engineering text, The Mythical Man Month (Brooks, n.d.).
As a result, and in awareness of Conway’s law, the implementation of this mandate also had a dramatic effect on Amazon’s organizational structure.
Because the design that occurs first is almost never the best possible, the prevailing system concept may need to change. Therefore, flexibility of organization is important to effective design.
Conway (n.d.)
Amazon is set up around the notion of the “two pizza team.” Teams of 6-10 people that can be theoretically fed by two (American) pizzas. This structure is tightly interconnected with the software. Each of these teams owns one of these “services.” Amazon is strict about the team that develops the service owning the service in production. This approach is the secret to their scale as a company, and the approach has been adopted by many other large tech companies. The software-as-a-service approach changed the information infrastructure of the company. The routes through which information is shared. This had a knock-on effect on the corporate culture.
Amazon works through an approach I think of as “devolved autonomy.” The culture of the company is widely taught (e.g. Customer Obsession, Ownership, Frugality), a team’s inputs and outputs are strictly defined, but within those parameters, teams have a great of autonomy in how they operate. The information infrastructure was devolved, so the autonomy was devolved. The different parts of Amazon are then bound together through shared corporate culture.
SaaS companies are information businesses. AI changes the topography of that information: more throughput, more interfaces, more automation of the middle of the stack. The Bezos API mandate is a useful reminder that when interfaces proliferate without clear ownership, the organisation fragments. Software firms that treat AI as a feature bolt-on will feel that fragmentation first.
Intellectual Debt in Software Organisations
Intellectual Debt
Figure: Jonathan Zittrain’s term to describe the challenges of explanation that come with AI is Intellectual Debt.
In the context of machine learning and complex systems, Jonathan Zittrain has coined the term “Intellectual Debt” to describe the challenge of understanding what you’ve created. In the ML@CL group we’ve been foucssing on developing the notion of a data-oriented architecture to deal with intellectual debt (Cabrera et al., 2023).
Zittrain points out the challenge around the lack of interpretability of individual ML models as the origin of intellectual debt. In machine learning I refer to work in this area as fairness, interpretability and transparency or FIT models. To an extent I agree with Zittrain, but if we understand the context and purpose of the decision making, I believe this is readily put right by the correct monitoring and retraining regime around the model. A concept I refer to as “progression testing.” Indeed, the best teams do this at the moment, and their failure to do it feels more of a matter of technical debt rather than intellectual, because arguably it is a maintenance task rather than an explanation task. After all, we have good statistical tools for interpreting individual models and decisions when we have the context. We can linearise around the operating point, we can perform counterfactual tests on the model. We can build empirical validation sets that explore fairness or accuracy of the model.
See Lawrence (2024) intellectual debt p. 84, 85, 349, 365.
Technical Debt
In computer systems the concept of technical debt has been surfaced by authors including Sculley et al. (2015). It is an important concept, that I think is somewhat hidden from the academic community, because it is a phenomenon that occurs when a computer software system is deployed.
Separation of Concerns
To construct such complex systems an approach known as “separation of concerns” has been developed. The idea is that you architect your system, which consists of a large-scale complex task, into a set of simpler tasks. Each of these tasks is separately implemented. This is known as the decomposition of the task.
This is where Jonathan Zittrain’s beautifully named term “intellectual debt” rises to the fore. Separation of concerns enables the construction of a complex system. But who is concerned with the overall system?
Technical debt is the inability to maintain your complex software system. Intellectual debt is the inability to explain your software system.
It is right there in our approach to software engineering. “Separation of concerns” means no one is concerned about the overall system itself.
See Lawrence (2024) separation of concerns p. 84-85, 103, 109, 199, 284, 371.
See Lawrence (2024) intellectual debt p. 84-85, 349, 365, 376.
Technical debt is familiar to every software CEO. Intellectual debt is the cousin that AI accelerates: systems that work, ship, and bill — but that nobody can fully explain. In a SaaS context that shows up as model-driven pricing, support bots, recommendation engines, and agentic workflows whose failure modes are opaque to the customer and to the board.
Where Superficial Automation Fails
Superficial Automation
The rise of AI has enabled automation of many surface-level tasks - what we might call “superficial automation.” These are tasks that appear complex but primarily involve reformatting or restructuring existing information, such as converting bullet points into prose, summarizing documents, or generating routine emails.
While such automation can increase immediate productivity, it risks missing the deeper value of these seemingly mundane tasks. For example, the process of composing an email isn’t just about converting thoughts into text - it’s about:
- Reflection time to properly consider the message
- Building relationships through personal communication
- Developing and refining ideas through the act of writing
- Creating institutional memory through thoughtful documentation
- Projecting corporate culture
When we automate these superficial aspects, we can create what appears to be a more efficient process, but one that gradually loses meaning without human involvement. It’s like having a meeting transcription without anyone actually attending the meeting - the words are there, but the value isn’t.
Consider email composition: An AI can convert bullet points into a polished email instantly, but this bypasses the valuable thinking time that comes with composition. The human “pause” in communication isn’t inefficiency - it’s often where the real value lies.
This points to a broader challenge with AI automation: the need to distinguish between tasks that are merely complex (and can be automated) versus those that are genuinely complicated (requiring human judgment and involvement). Effective deployment of AI requires understanding this distinction and preserving the human elements that give business processes their true value.
The risk is creating what appears to be a more efficient system but is actually a hollow process - one that moves faster but creates less real value. True digital transformation isn’t about removing humans from the loop, but about augmenting human capabilities while preserving the essential human elements that give work its meaning and effectiveness.
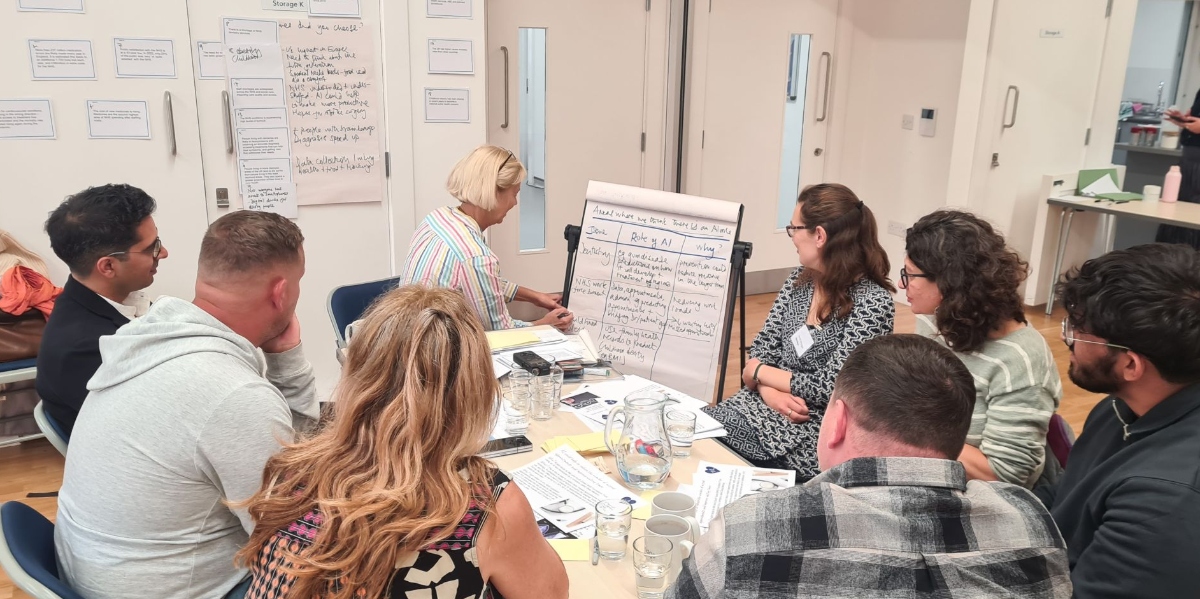
Figure: Public dialogue held in Liverpool alongside the 2024 Labour Party Conference. The process of discussion is as important as the material discussed. In line with previous dialogues attendees urged us to develop technology where AI operates as a tool for human augmentation, not replacement.
In our public dialogues we saw the same theme: good process can drive purpose. Discussion is as important as the conclusions reached. Attendees urged us to develop technology where AI operates as a tool for human augmentation, not replacement.
Atrophy and Cognitive Flattening
Even if we calibrate these tools correctly so that they do represent the world appropriately we are at risk. The hippocampus is part of our brain’s cortex, one role of our hippocampus is in navigation, knowing how to move from one place to another.
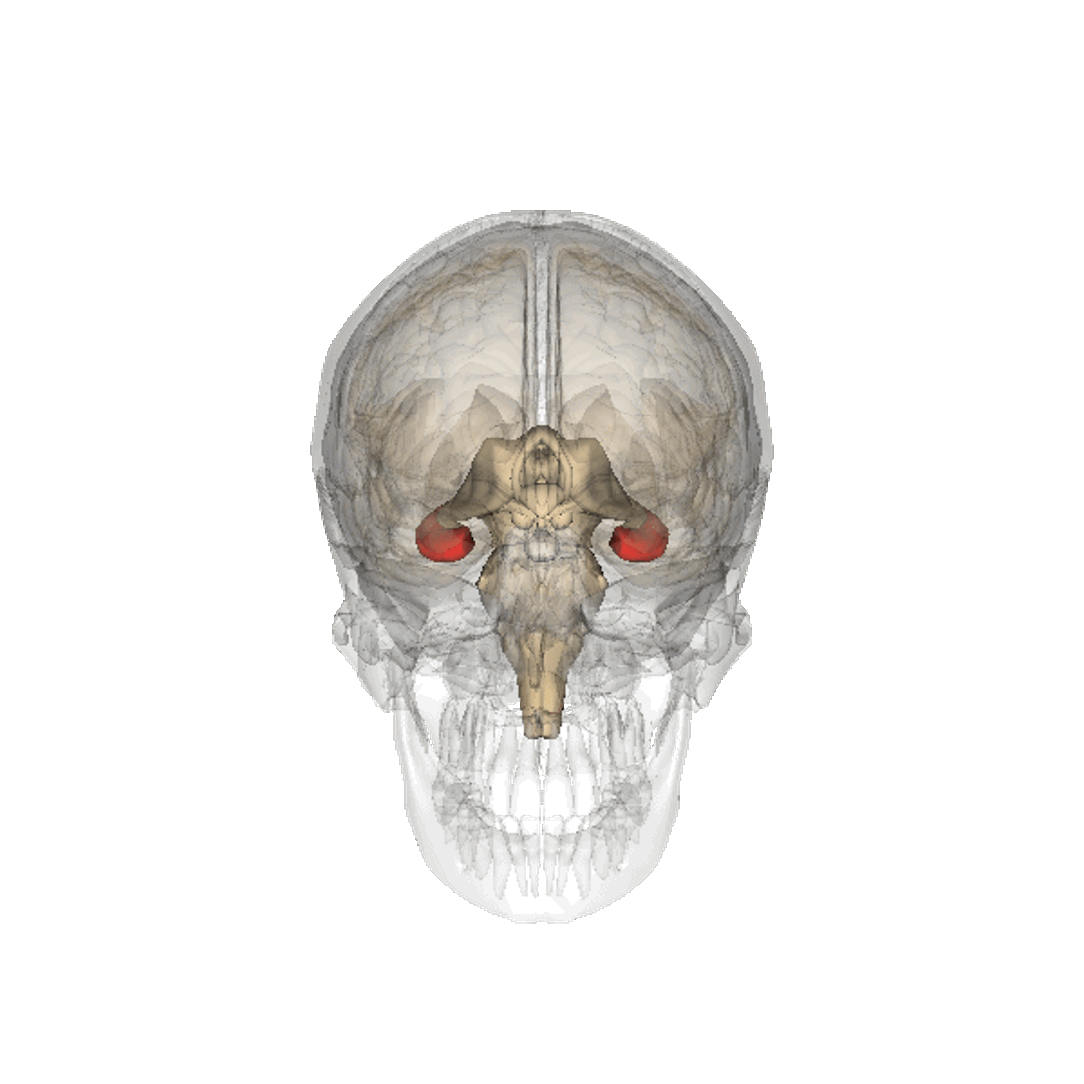
Figure: The hippocampus within the brain. Image generated from Anatomography, https://lifesciencedb.jp/.
Our prefrontal cortex, the size of which differentiates us from other primates and mammals, is the seat of our planning and of our higher intelligence. It fires in sympathy with our hippocampus.
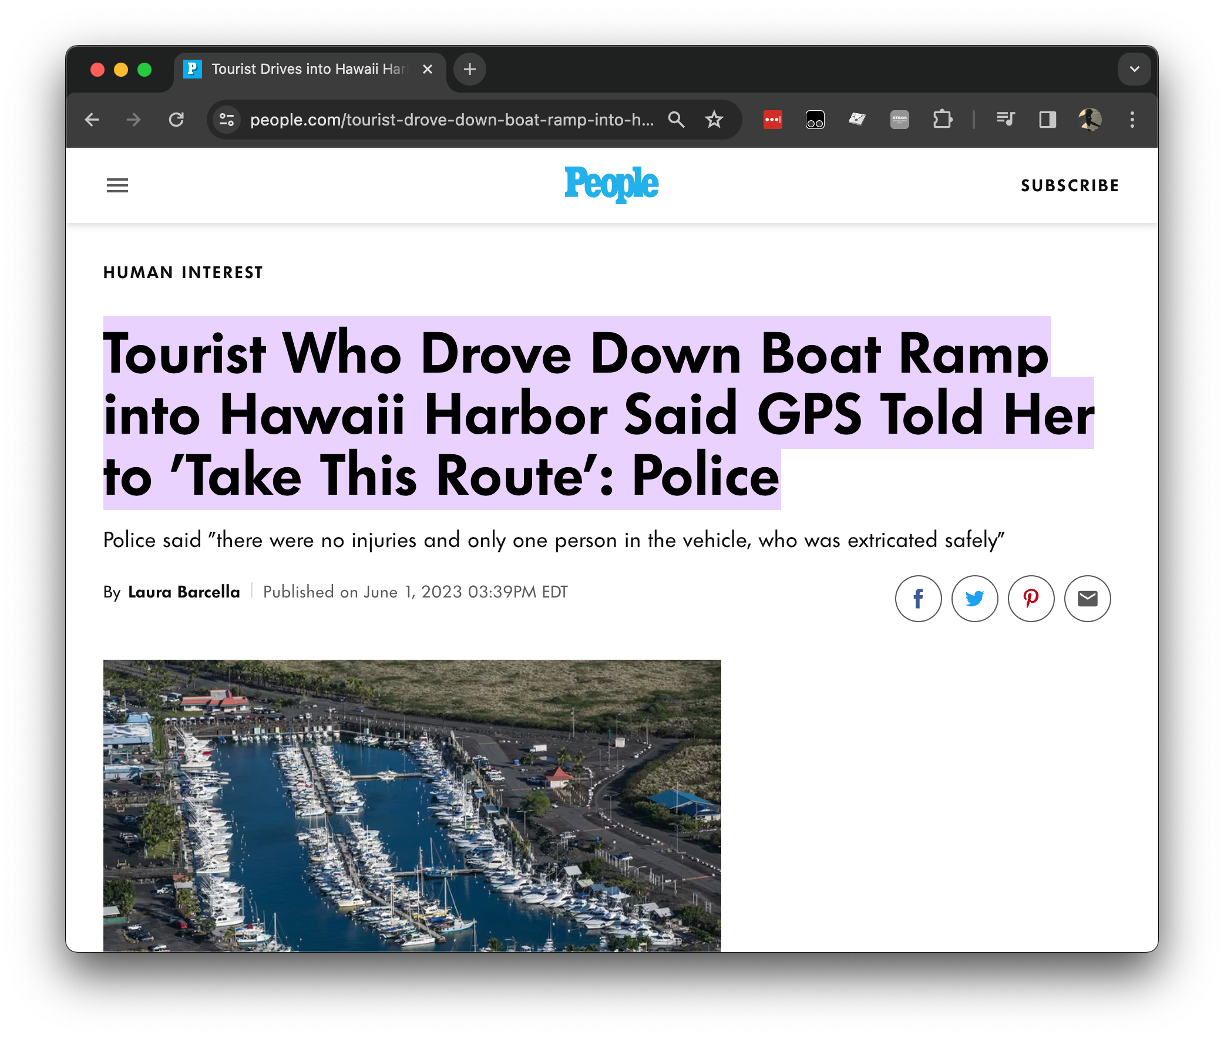
Figure: Navigation is helpful but we can become overreliant on it. News article from people.com.
By becoming overreliant on HAMs and there interface to the digital computer are we at risk of suffering from the same deskilling we perceive in our navigational skills? Does this place us at risk of sleepwalking into a world that is managed by the machine even as we believe that we are managing it ourselves?
Much of the current SaaS AI wave automates the visible surface — ticket summaries, CRM notes, code autocomplete — while leaving the underlying decision problem untouched. Done well, that frees attention. Done badly, it flattens cognition inside the firm: juniors stop learning, seniors stop reviewing, and the company loses the expertise that made the product valuable.

Figure: The innovator’s dilemma explains the challenge of being the incumbent business with refined processes, but not being agile enough to respond when new technology arrives. This is what keeps the little Jeff in my head awake at night.
Incumbent SaaS firms face Christensen’s dilemma in a new form. Their processes are optimised for a world where software was scarce. AI makes software abundant. The firms that win will not simply add AI features to existing suites; they will rethink packaging, pricing, and the human work that surrounds the product.
A Warning on Trust
The Horizon scandal
In the UK we saw these effects play out in the Horizon scandal: the accounting system of the national postal service was computerized by Fujitsu and first installed in 1999, but neither the Post Office nor Fujitsu were able to control the system they had deployed. When it went wrong individual sub postmasters were blamed for the systems’ errors. Over the next two decades they were prosecuted and jailed leaving lives ruined in the wake of the machine’s mistakes.
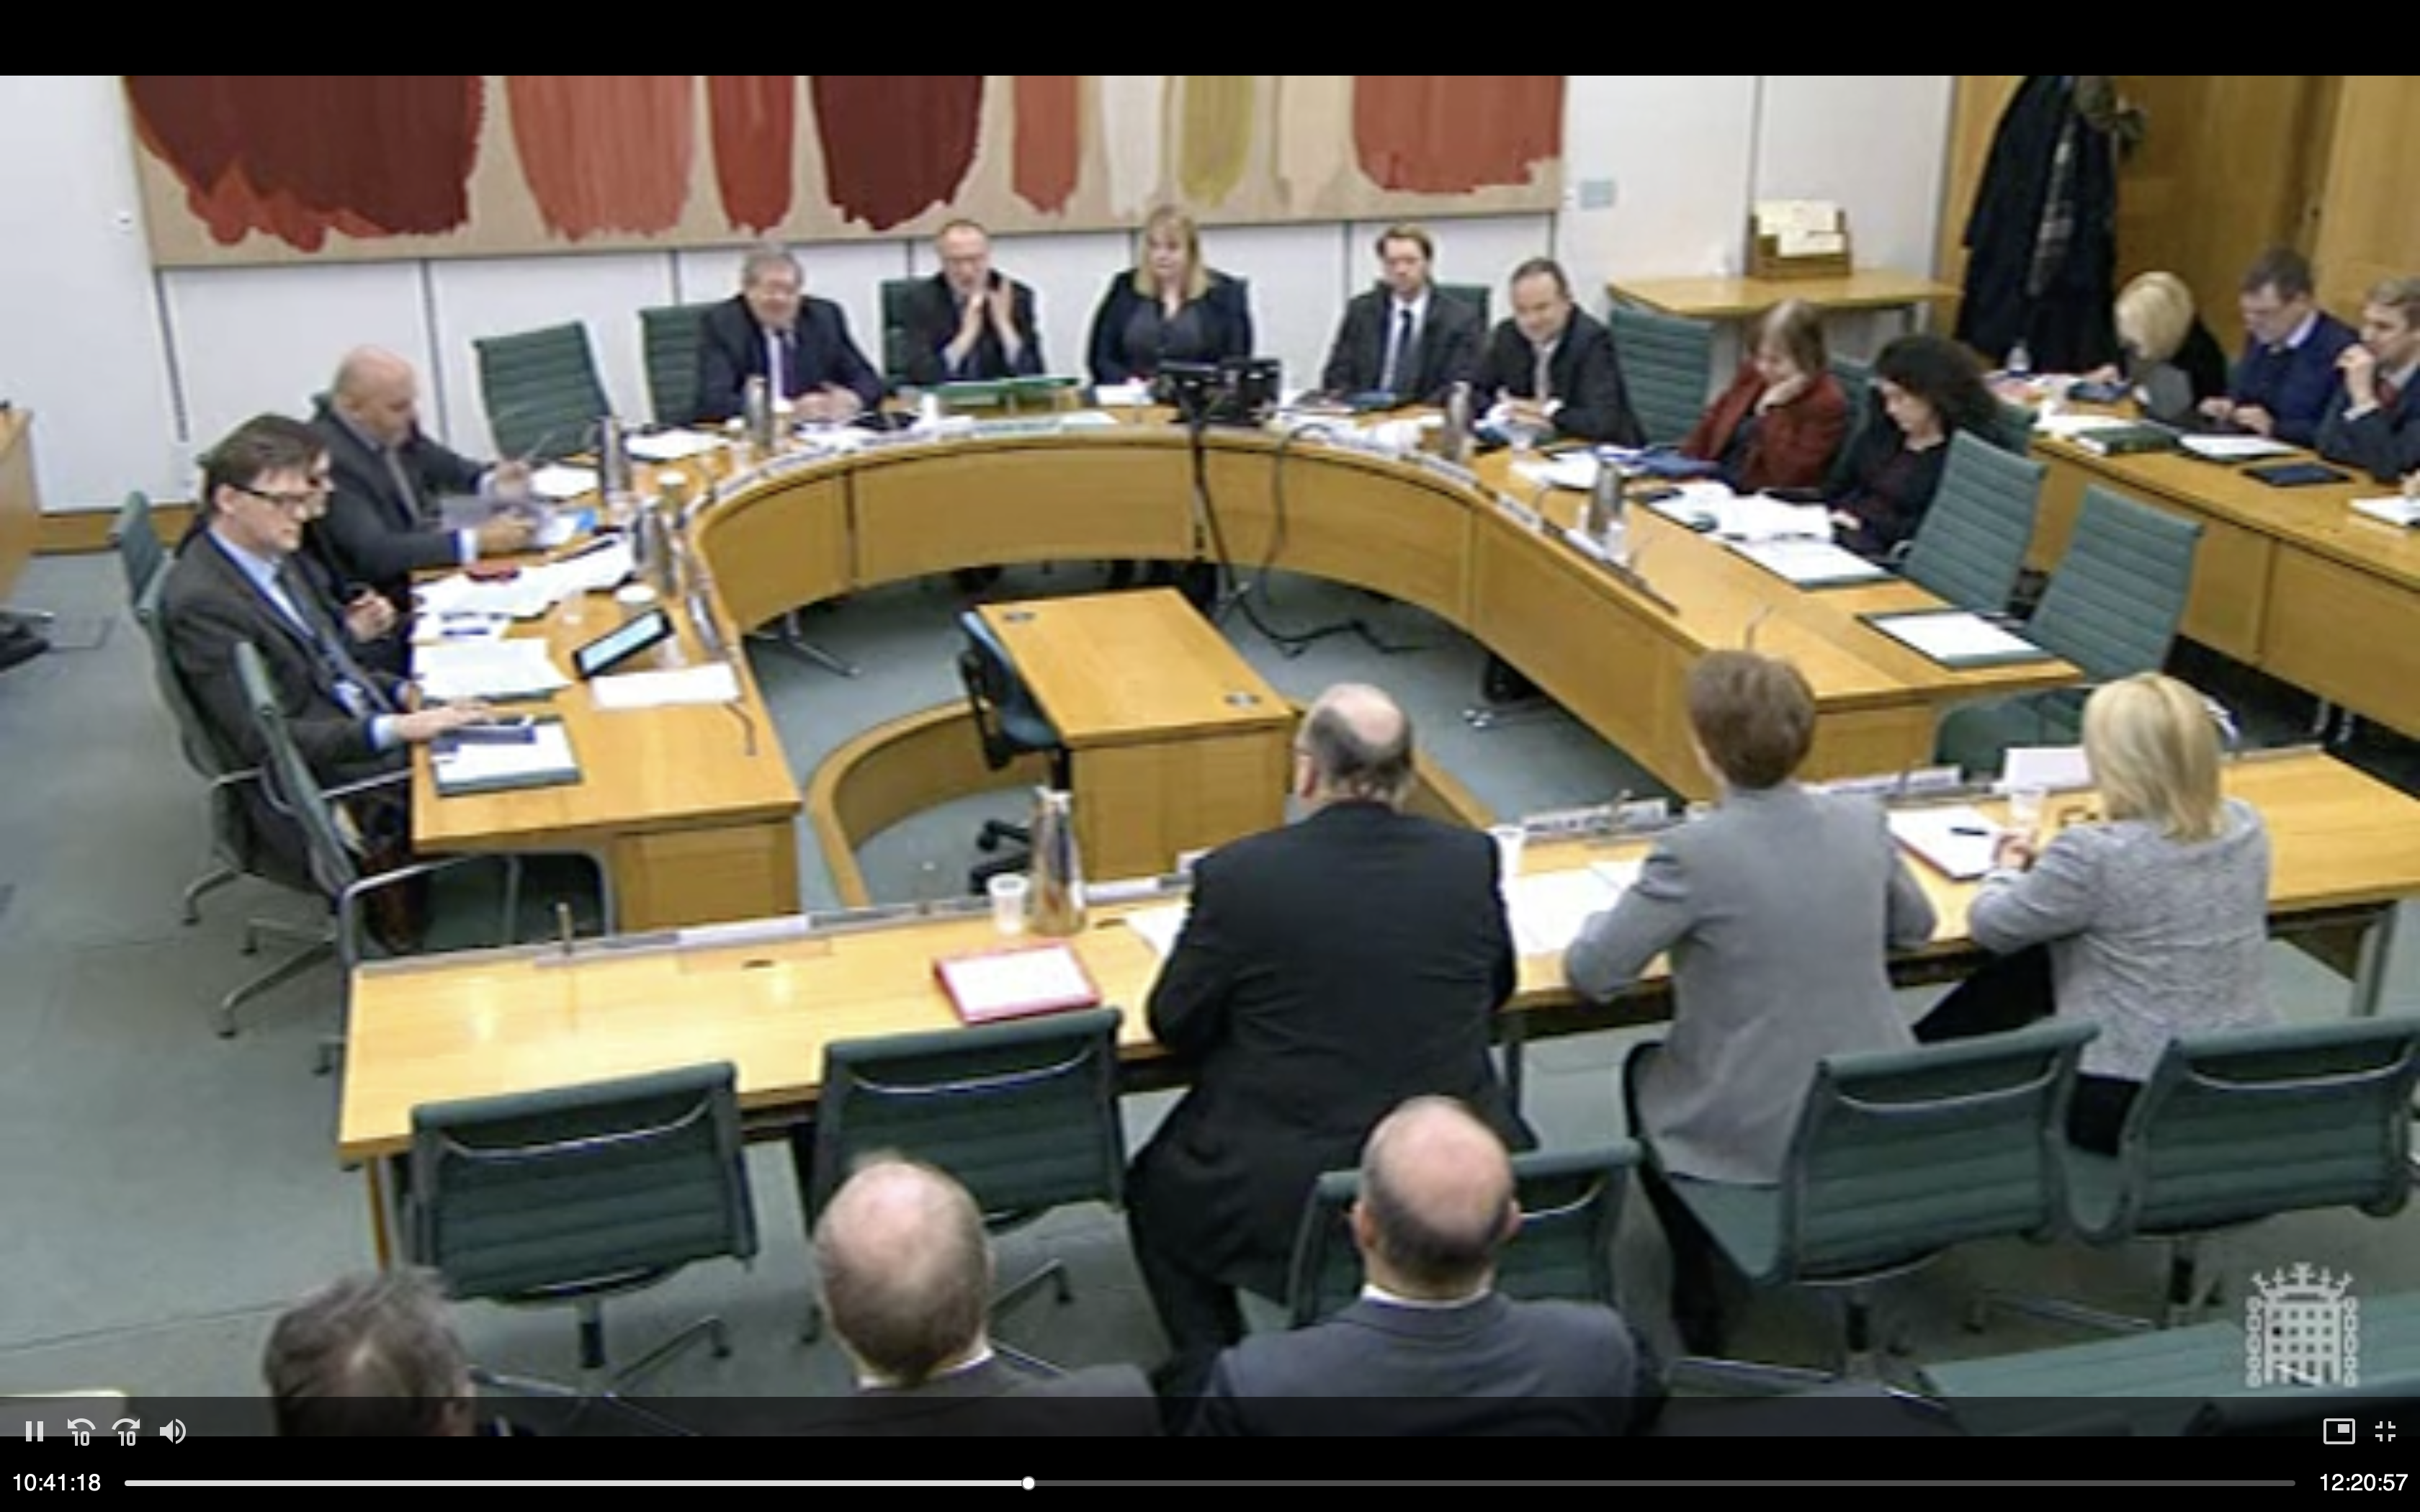
Figure: The still is from the 2015 select committee.
See Lawrence (2024) Horizon scandal p. 371.
Horizon is not a SaaS story, but it is a software story. When organisations subordinate human judgment to system outputs, trust collapses. For B2B software businesses selling into regulated or mission-critical environments, intelligent accountability is part of the product — not a compliance afterthought. Horizon is what happens when the judgment layer is present on paper but absent in practice.
Part 3: How the Industry May Evolve
Looking forward, the important shift is not that machines become digital humans. It is that human-analogue machines change the interface between people and software — and therefore the shape of the firm.
Human Analogue Machine
Recent breakthroughs in generative models, particularly large language models, have enabled machines that, for the first time, can converse plausibly with other humans.
The Apollo guidance computer provided Armstrong with an analogy when he landed it on the Moon. He controlled it through a stick which provided him with an analogy. The analogy is based in the experience that Amelia Earhart had when she flew her plane. Armstrong’s control exploited his experience as a test pilot flying planes that had control columns which were directly connected to their control surfaces.
Figure: The human analogue machine is the new interface that large language models have enabled the human to present. It has the capabilities of the computer in terms of communication, but it appears to present a “human face” to the user in terms of its ability to communicate on our terms. (Image quite obviously not drawn by generative AI!)
The generative systems we have produced do not provide us with the “AI” of science fiction. Because their intelligence is based on emulating human knowledge. Through being forced to reproduce our literature and our art they have developed aspects which are analogous to the cultural proxy truths we use to describe our world.
These machines are to humans what the MONIAC was the British economy. Not a replacement, but an analogue computer that captures some aspects of humanity while providing advantages of high bandwidth of the machine.
See Lawrence (2024) ignorance: HAMs p. 347. See Lawrence (2024) test pilot p. 163-8, 189, 190, 192-3, 196, 197, 200, 211, 245.
HAM
The Human-Analogue Machine or HAM therefore provides a route through which we could better understand our world through improving the way we interact with machines.
Figure: The trinity of human, data, and computer, and highlights the modern phenomenon. The communication channel between computer and data now has an extremely high bandwidth. The channel between human and computer and the channel between data and human is narrow. New direction of information flow, information is reaching us mediated by the computer. The focus on classical statistics reflected the importance of the direct communication between human and data. The modern challenges of data science emerge when that relationship is being mediated by the machine.
The HAM can provide an interface between the digital computer and the human allowing humans to work closely with computers regardless of their understandin gf the more technical parts of software engineering.
Figure: The HAM now sits between us and the traditional digital computer.
Of course this route provides new routes for manipulation, new ways in which the machine can undermine our autonomy or exploit our cognitive foibles. The major challenge we face is steering between these worlds where we gain the advantage of the computer’s bandwidth without undermining our culture and individual autonomy.
See Lawrence (2024) human-analogue machine (HAMs) p. 343-347, 359-359, 365-368.
Productivity Flywheel
Figure: The productivity flywheel suggests technical innovation is reinvested.
The productivity flywheel should return the gains released by productivity through funding. This relies on the economic value mapping the underlying value.
Attention Reinvestment Cycle
Figure: The attention flywheel focusses on reinvesting human capital.
While the traditional productivity flywheel focuses on reinvesting financial capital, the attention flywheel focuses on reinvesting human capital - our most precious resource in an AI-augmented world. This requires deliberately creating systems that capture the value of freed attention and channel it toward human-centered activities that machines cannot replicate.
Classical SaaS flywheels reinvest capital into sales and R&D. In the AI era the scarce input is human attention — of your engineers, your customers, and your operators. Firms that free attention and then waste it on more shallow automation will not compound. Firms that reinvest attention into judgment, relationships, and new product categories will.
AI cannot replace atomic human
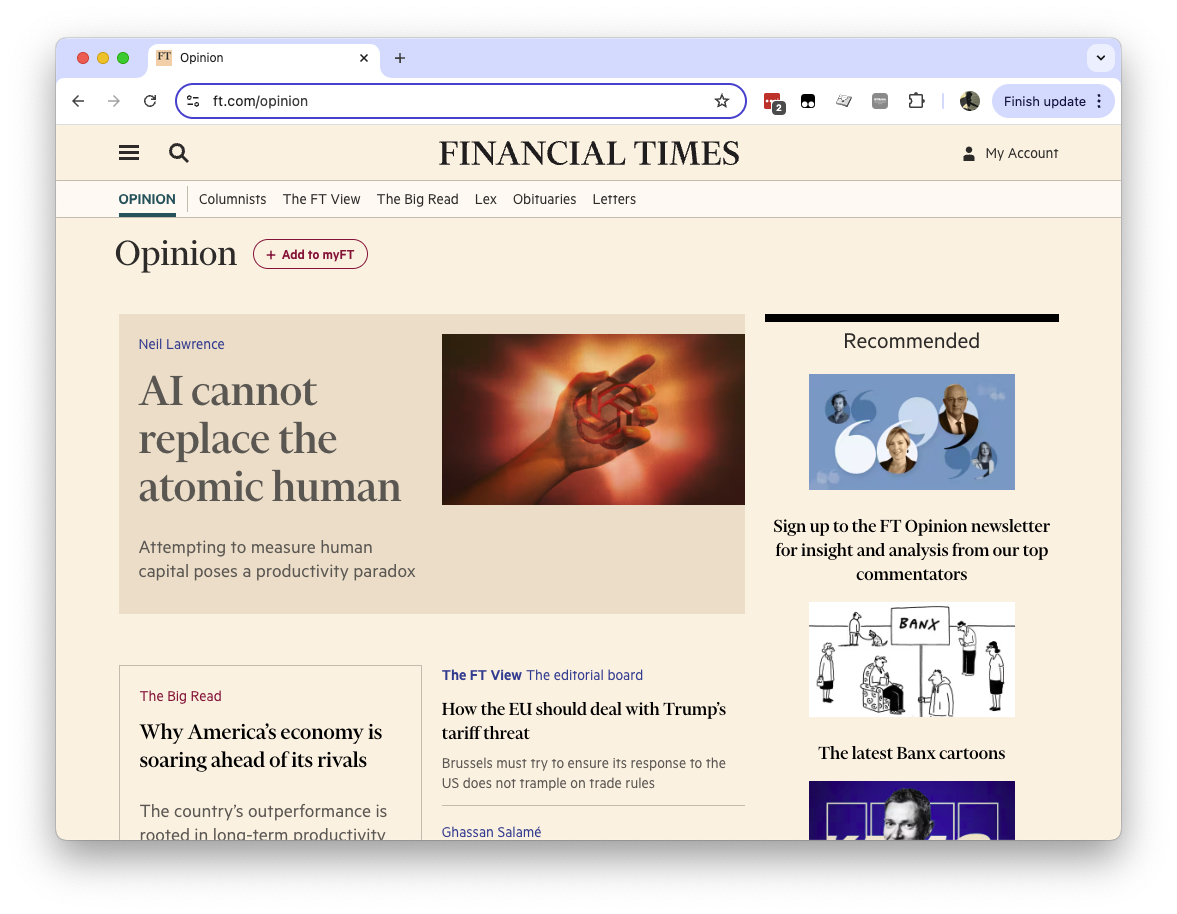
Figure: Opinion piece in the FT that describes the idea of a social flywheel to drive the targeted growth we need in AI innovation.
The FT piece — AI cannot replace the atomic human — is the shortest public statement of this point. Attempting to measure human capital poses a productivity paradox: what machines can quantify, they can automate. The remainder that matters for software businesses is judgment, trust, and care for the customer problem — the atomic human contribution that does not inflate away.
Agentic Debt
Agentic AI could pay down the technical debt and intellectual debt that plauges our deployment of complex systems. But in doing so it could create a new form of debt: agentic debt.
Agentic debt is the “new debt” introduced by systems that can act: the accrued risk and cost of operating delegated workflows without crisp boundaries. Unlike technical debt, e.g. emerging from engineering shortcuts, and intellectual debt emerging from (well engineered) complex systems, agentic debt is about unsafe or illegible delegation. Who (or what) can cause what action, on what evidence, with what recovery path?
Agentic systems — systems that can act inside workflows — may pay down technical and intellectual debt. They can also create agentic debt: delegation without clear authority, evidence, or recovery. For software CEOs and their investors, the governance question becomes: who or what can cause what action, on what basis, with what stop-condition?
The Judgment Layer
This is the pivot. Once agents execute real workflows, advantage and safety stop being model properties and become organisational ones. The right question is not how to make the model produce the right answer. It is who has the authority to decide when the answer matters.
Judgment Layer: Organisations as emulsions
Think of an organisation as an emulsion. One phase is the automatable routines — rule-based decisions, standard workflows, repeatable processes. The other phase is the irreducible human context — tacit norms, exceptions, escalation paths, and situational awareness that rarely makes it into documentation. In a healthy organisation these two phases are held in a stable mixture. The judgment layer is the interface between them: the decisions that route a situation from routine handling to human attention.
When we automate workflows with agentic AI, we are in effect trying to distil the automatable phase and hand it to a system. But the emulsion is mixed: the judgment calls are tangled up with the routine steps. Automating without first extracting and formalising those judgment calls does not eliminate them — it just makes them invisible. That invisibility is agentic debt.
The judgment layer is not one decision but a distributed set of micro-interventions embedded in the fabric of how work flows through an organisation. Security teams accumulate this knowledge over years: which alerts are usually noise, which anomalies are actually fine because of a known upstream cause, which vendor exceptions are pre-approved. None of it is written down. It lives in the heads of experienced operators and in the patterns of who emails whom when something looks off.
For a security context, this is especially acute. The same log pattern can be routine or catastrophic depending on context that is not in the log. The judgment layer is the part of the organisation that holds that context.
The Good Regulator Theorem
Conant and Ashby: a regulator that successfully holds a system within bounds must, in effect, contain a model of that system (Conant and Ashby, 1970). An information-theoretic reading is that optimal regulation supports \(H(R|S)=0\) — the regulator’s action can be a deterministic function of system state. The practical reading for commercial leaders is sharper. If institutional judgement is still meant to regulate automated and agentic systems, those systems must remain modellable by the people who own the risk. Opacity is not merely an explainability preference; it is a failure of the regulator condition.
Model minimisation is the engineering corollary of the Good Regulator theorem. It is not aesthetic minimalism and not anti-capability. Capability that cannot be modelled by the judgement layer is capability the institution cannot regulate. The unit of design is the judgement-preserving interface — including an explicit abstain / escalate path.
Across cybernetics and organisational science this is the same object: Beer’s live regulator (Beer, 1979, 1972); Ashby’s law of requisite variety (Ashby, 1956); uncertainty absorption and exception handling (March and Simon, 1958); Galbraith’s information-processing view of organisation design (Galbraith, 1974); and the boundary between routine cases and escalated cases in knowledge hierarchies (Garicano, 2000). Agentic AI puts new stress on it because language becomes action at machine speed.
The Good Regulator theorem makes the constraint precise: every good regulator must contain a model of what it regulates. Humans model not just the software but the organisation — priorities, risk, history, customers, people. Automating without preserving that judgment makes it invisible, not absent. That invisibility is agentic debt. The more autonomous AI becomes, the more valuable this judgment becomes — not less.
A short forward look for the room. As code generation and workflow automation spread, the marginal cost of software production falls. That pressures seat-based SaaS economics and elevates everything around the code: proprietary data, distribution, customer trust, and the judgment to know what should be built — and when to halt. Private equity and founders should underwrite the judgment layer as carefully as the model layer.
AI arrives workflow by workflow
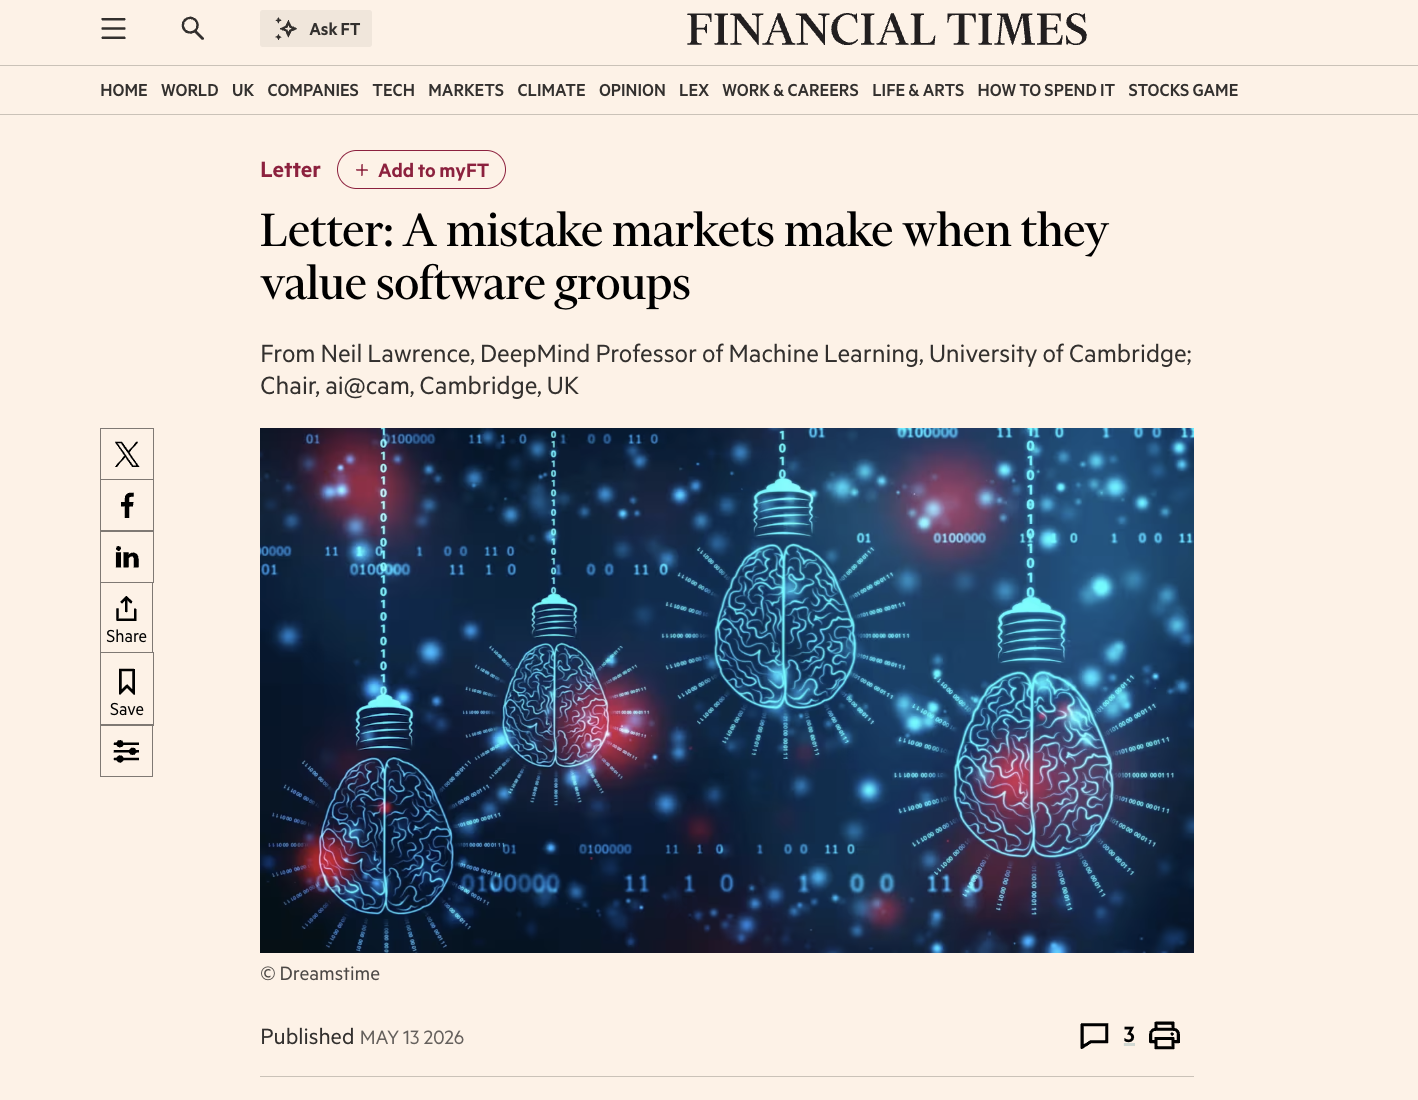
Figure: Letter in the FT: AI arrives workflow by workflow — markets err when they value software groups as if AI were one centralised deployment.
In a letter to the Financial Times (12 May 2026), I replied to reporting on Visma’s postponed IPO and to the question whether a group of some 170 businesses can “create the operational change centrally” for AI. That premise is wrong. AI is not one thing applied once from the centre. A payroll team in Oslo and a tax team in Lisbon face different regulations, customers and data. Federated structures, properly supported, sit closer to where that value is made — not further from it.
For software CEOs, founders and investors, the letter is a diligence filter. Seat counts and model features are easy to aggregate. Workflow-level adoption, with explicit judgment and recovery paths, is harder — and that is where durable value sits. The same confusion appears in policy when compute and frontier models are privileged over how people adopt tools inside their own institutions.
A mistake markets make when they value software groups
The FT letter is aimed at this room. Markets err when they value software groups as if AI were one centralised programme. Value arrives workflow by workflow, in the hands of people who understand the work. That is another way of saying: protect and productise the local judgment layer — do not assume the centre can create the operational change once for all.
The Atomic Human
Figure: The Atomic Human (Lawrence, 2024).
Close: Trent and the Judgment Layer in Practice
I will close with what we are building. The argument of this talk is not only diagnostic. At Trent we treat the judgment layer as a first-class architectural component — separating it from automated execution and delivering it to the AI-augmented engineer.
Why did I start Trent?
Figure: Trent.ai is a company co-founded with Zhenwen Dai and Eno Thereska that is working at the interface of agentic AI and complex software systems.
At trent.ai we are putting this into practice by working closely with the People who are close to the Systems. We are addressing real pain points now. But ensuring we have a view on the long term change that comes with this radical disruption to our information systems. We are doing this by bridging in to the best agentic AI technology, both our proprietary work and commercial tools.
Drawing on the line from the Agentic AI Summit: we need the judgment layer separated, the authority of the AI-augmented engineer preserved, and the system built to deliver both. That is the organisational framing of AI safety — and, for software businesses, of durable advantage. Trent works with people who are close to complex systems, addressing pain points now while holding a view on the long-term redesign of information systems under agentic AI.
Open for Q&A. Prefer concrete product, pricing, and diligence examples from the room. Useful threads: seat vs outcome pricing; build-vs-buy for models; how PE diligence should treat AI features; where customer trust breaks when agents act on a user’s behalf; how to make escalation / “I don’t know” a first-class product behaviour.
Thanks!
For more information on these subjects and more you might want to check the following resources.
- company: Trent AI
- book: The Atomic Human
- twitter: @lawrennd
- podcast: The Talking Machines
- newspaper: Guardian Profile Page
- blog: http://inverseprobability.com